AI Architecture #113
Generative AI
original term: generative AI (Eng.) · sztuczna inteligencja generatywna, GenAI, modele generatywne
Central European lineage: 3 threads (author from the region, anticipation) · 1965–2017 · jump to documentation ↓
Working Definition
Generative AI (GenAI) is a class of machine-learning systems that, after learning the underlying probability distribution of a massive dataset, synthesize novel artifacts sampled from that distribution—including text, source code, images, audio, video, and 3D or molecular structures. Technically, it is defined in contrast to discriminative or predictive AI: rather than mapping an input to an existing category label or numerical score (“is this transaction fraudulent?”, “is there a tumor on this scan?”), a generative model answers “what token, pixel patch, or audio frame is most likely to come next given this conditioning prompt?” In everyday and commercial usage since late 2022, the phrase simply designates consumer-facing products like ChatGPT, Midjourney, or Sora, obscuring the fact that “generativity” describes a statistical sampling regime rather than a distinct species of machine consciousness. Holding onto the technical definition is essential because the characteristic failure modes of these systems—such as confident fabrication—follow directly from probabilistic sampling.
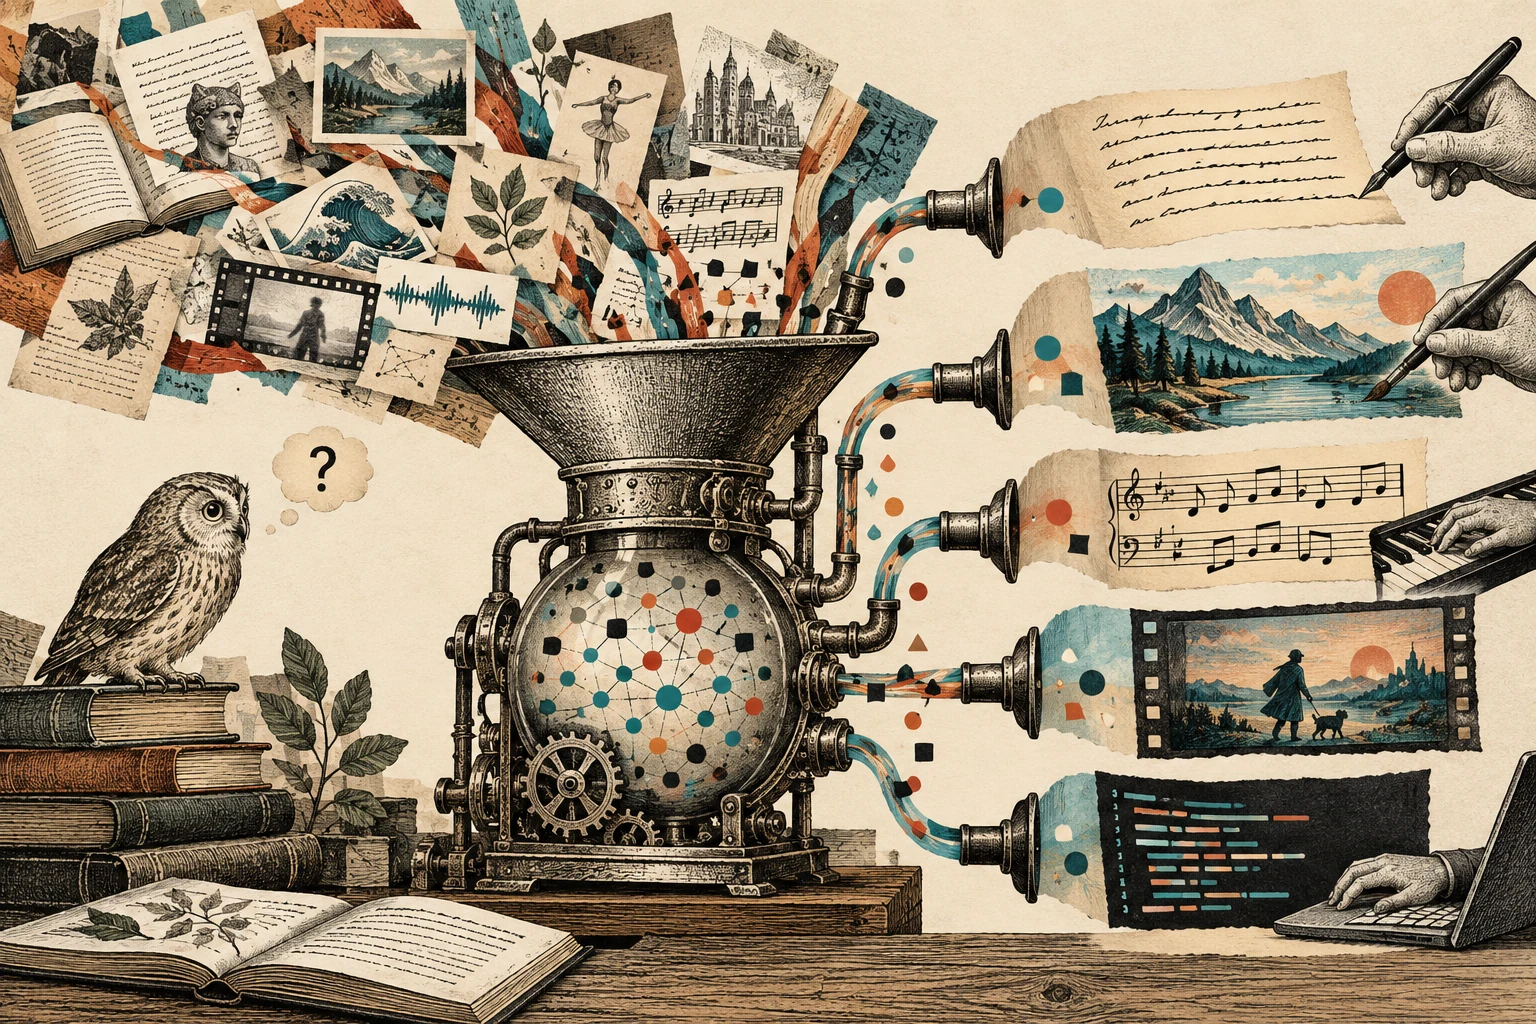
Learned regularities are used to produce new text, images, or audio; generation is neither simple copying nor a guarantee of originality or truth.
AI-assisted illustration · conceptual metaphor View in visual quiz →Genesis and Global Lineage
The concept rests on three historical layers. The oldest is mathematical statistics: statisticians long distinguished generative models (modeling the joint distribution P(X, Y) or P(X) and sampling synthetic data points) from discriminative models (estimating only the decision boundary P(Y | X)). The second layer is the deep-learning wave of 2010–2017: recurrent neural network language models for next-word prediction (Mikolov et al., 2010), Variational Autoencoders (Kingma and Welling, 2013), Generative Adversarial Networks (GANs, Goodfellow et al., 2014), denoising diffusion models (Sohl-Dickstein et al., 2015; Ho et al., 2020), and the Transformer (Vaswani et al., 2017), which unlocked web-scale pretraining. The third layer is productization and venture-capital branding: OpenAI’s GPT series (2018–2020) and DALL-E (2021), followed in summer 2022 by Midjourney and open-weight Stable Diffusion (Rombach et al., August 2022), culminating in ChatGPT (November 2022). Only in autumn 2022—through venture-capital essays (like Sequoia Capital’s September 2022 market map) and press coverage—did “generative AI” solidify as the umbrella label for the entire wave, subtly distorting public understanding by equating all of AI with content synthesis even though most industrial and medical AI systems remain discriminative classifiers.
Central European Lineage
The concept connects to Central Europe through two documented technical lineages and one literary anticipation. The strongest technical thread leads to Brno, Czechia: at the Faculty of Information Technology of the Brno University of Technology (VUT), doctoral researcher Tomáš Mikolov and Jan Černocký’s Speech@FIT group published Recurrent neural network based language model at Interspeech 2010, showing that a neural network maintaining context in a continuous hidden state predicts the next word far better than classic n-gram tables—the exact autoregressive objective modern text generators scale up. A second technical thread runs through the June 2017 Transformer paper (Attention Is All You Need), whose eight co-authors include University of Wrocław–educated computer scientist Łukasz Kaiser and Kharkiv Polytechnic alumnus Illia Polosukhin. Alongside these engineering links stands a philosophical anticipation from Kraków: in his 1965 story collection Cyberiada (The Cyberiad, translated by Michael Kandel in 1974), Stanisław Lem described Elektrybałt (“Trurl’s Electronic Bard”)—a machine commissioned to generate poetry on any prompt and in any style. In Lem’s fable, Trurl discovers that to generate convincing verse, he must first initialize the machine with a simulation of the entire evolutionary and cultural history that produced human language—whereupon its effortless output drives human poets to despair.
Documented regional lineage · Links: 3. Compiled: October 2026.
-
anticipation 49 years
Central European Source: Stanisław Lem, “Wyprawa pierwsza A, czyli Elektrybałt Trurla (w: Cyberiada)”; Kraków, Poland, 1965
Global Circulation: generative AI (machines composing original texts on any prompted topic or style) — Ian Goodfellow i in. (GAN, 2014); OpenAI (GPT, 2018–2022), 2014
-
author from the region 0 years — same text on both sides
Central European Source: Tomáš Mikolov, “Recurrent neural network based language model”; Brno, Czechoslovakia (now Czechia), 2010
Global Circulation: neural language models as the core of text-based generative AI — Tomáš Mikolov, Martin Karafiát, Lukáš Burget, Jan Černocký, Sanjeev Khudanpur, 2010
-
author from the region 4 years
Central European Source: Łukasz Kaiser, “Wrocław: urodzenie (1981), habilitacja na Uniwersytecie Wrocławskim (2013) przed pracą w Google Brain”; Wrocław, Poland, 2013
Global Circulation: Transformer (Attention Is All You Need) — the architecture underlying contemporary generative models — Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N. Gomez, Łukasz Kaiser, Illia Polosukhin, 2017
author from the region
0 years — same text on both sidesTomáš Mikolov, “Recurrent neural network based language model”
2010 · Brno, Czechoslovakia (now Czechia)
neural language models as the core of text-based generative AI
2010 · Tomáš Mikolov, Martin Karafiát, Lukáš Burget, Jan Černocký, Sanjeev Khudanpur
- Claim & Connection
- Mikolov, then a doctoral student in the Speech@FIT group at the Brno University of Technology (PhD 2012), presented at Interspeech 2010 a recurrent neural network language model that predicts the next word from context preserved in the network's hidden state. The task of autoregressive next-word prediction is the exact objective scaled up by contemporary generative text models; the paper was produced at VUT Brno in collaboration with Johns Hopkins University.
- Source Documentation
-
- primary source Tomáš Mikolov, Martin Karafiát, Lukáš Burget, Jan Černocký, Sanjeev Khudanpur, „Recurrent neural network based language model”, Interspeech 2010, s. 1045–1048; header: Speech@FIT affiliation, Brno University of Technology; abstract. isca-archive.org ↗
- biographical record Wikipedia (en), „Tomáš Mikolov”; paragraph on studies and doctorate (Brno University of Technology, 2012) and the 2010 RNN LM. en.wikipedia.org ↗
- Historical Context
- This link concerns generative text modeling specifically rather than the entire multimodal umbrella (image, audio, video). Mikolov published his subsequent word2vec work (2013) after joining Google.
author from the region
4 yearsŁukasz Kaiser, “Wrocław: urodzenie (1981), habilitacja na Uniwersytecie Wrocławskim (2013) przed pracą w Google Brain”
2013 · Wrocław, Poland
Transformer (Attention Is All You Need) — the architecture underlying contemporary generative models
2017 · Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N. Gomez, Łukasz Kaiser, Illia Polosukhin
- Claim & Connection
- Kaiser is one of the eight co-authors of the June 2017 paper that introduced the Transformer architecture, the foundation of the GPT series and the vast majority of contemporary generative AI models. Open sources confirm his birth in Wrocław, graduation and post-doctoral habilitation at the University of Wrocław in 2013, and PhD at RWTH Aachen (2008) prior to joining Google Brain in 2013.
- Source Documentation
-
- primary source Ashish Vaswani i in., „Attention Is All You Need”, arXiv:1706.03762, 12 czerwca 2017; author list, abstract. arxiv.org ↗
- biographical record Wikipedia (pl), „Łukasz Kaiser”; paragraph on PhD (RWTH Aachen 2008), habilitation (University of Wrocław 2013), Google Brain (2013), and OpenAI (2021). pl.wikipedia.org ↗
- Historical Context
- Co-author Illia Polosukhin was educated in Kharkiv, Ukraine (documented in the Transformer briefing).
anticipation
49 yearsStanisław Lem, “Wyprawa pierwsza A, czyli Elektrybałt Trurla (w: Cyberiada)”
1965 · Kraków, Poland
generative AI (machines composing original texts on any prompted topic or style)
2014 · Ian Goodfellow i in. (GAN, 2014); OpenAI (GPT, 2018–2022)
- Claim & Connection
- In 1965, Stanisław Lem published a philosophical fable about a machine (“Elektrybałt” / Trurl's Electronic Bard) that composes poetry on any prompted topic and in any requested style—and whose construction requires its builder to first model the entire cosmic and cultural history out of which human language grew. This stands as a striking literary anticipation of generative systems sampling from a compressed representation of all human culture, though without documented influence on later machine-learning engineering.
- Source Documentation
-
- bibliographic record Wikipedia (en), „The Cyberiad”; publication details of first Polish edition (Wydawnictwo Literackie 1965), the story “The First Sally (A), or Trurl’s Electronic Bard”, and Michael Kandel's English translation (Harcourt Brace 1974). en.wikipedia.org ↗
- bibliographic record Wikipedia (pl), „Cyberiada”; table of contents: “Wyprawa pierwsza A, czyli Elektrybałt Trurla”. pl.wikipedia.org ↗
- Historical Context
- Literary anticipation rather than documented engineering influence; Kandel's 1974 English translation “The Cyberiad” circulated widely among American computer scientists and cognitive philosophers (including Douglas Hofstadter).
Why Now
November 2022 marked the inflection point when generative AI crossed from preprints into mass socioeconomic reality: within ninety days of Stable Diffusion (August 2022) and ChatGPT (November 2022), hundreds of millions of users were generating essays, code, and illustrations on demand. By 2023, the shock triggered landmark copyright litigation in the US and Europe—including lawsuits by the Authors Guild, Getty Images, and The New York Times against OpenAI, Microsoft, and Stability AI—challenging whether unlicensed training on copyrighted works constitutes fair use. Simultaneously, the 2023 Hollywood writers’ (WGA) and actors’ (SAG-AFTRA) strikes secured the first union guardrails against replacing performers with synthetic replicas or reducing writers to editors of AI drafts. In the European Union, the AI Act (in force August 2024; GPAI rules applicable from August 2025) imposed duties to disclose training-data summaries, respect copyright opt-outs, and label synthetic media. Between 2024 and 2026, rapid proliferation created urgent second-order problems: “AI slop” clogging search and social feeds, “model collapse” when newer models ingest synthetic outputs, and Wall Street scrutiny over whether trillions in GPU capital expenditure will yield matching productivity gains.
Explanatory Power
The concept explains what happens when the marginal cost of producing plausible human-like expression drops to near zero. First, it explains why automated “AI detectors” in schools and journalism fail systematically: because a generative model samples directly from the statistical distribution of human writing, the better it becomes, the closer its output converges to human work—while detectors penalize non-native speakers and formulaic human prose with high false-positive rates. Second, it clarifies why factual hallucinations cannot be “fixed” by a simple patch: a model sampling high-probability continuations in latent space does not consult an internal database of verified facts unless bolted onto an external retrieval system (like RAG). Third, it exposes a structural crisis in copyright and labor law: traditional IP polices verbatim copying of fragments, whereas a generative model extracts the statistical regularities of a creator’s entire body of work to compete directly against them in the market without reproducing any single sentence verbatim.
Axes of Debate
Statistical pattern synthesis versus genuine world understanding
Computational linguists and critical AI scholars (Emily M. Bender, Timnit Gebru et al., 2021; Gary Marcus) argue that generative models manipulate surface distributions of tokens and pixels without grounding in communicative intent, causal physics, or truth—making claims of “creativity” or “reasoning” a category mistake. Deep-learning and interpretability researchers counter that compressing petabytes of multimodal data forces the network to learn rich internal representations of syntax, spatial geometry, and human psychology. Strongest counterargument: Even when internal probes reveal structured representations inside large models, generative systems still exhibit brittle, non-human failures—inventing nonexistent court precedents or reversing causal logic under slight phrasing shifts—showing that statistical plausibility and grounded truth remain distinct regimes. Nature of the dispute: mixed — empirical probing of network circuits is substantive, whereas public debates over whether the output counts as “true creativity” are philosophical and rhetorical.
Unlicensed training on human culture: fair learning or industrial theft?
Tech companies and permissive-copyright scholars argue that ingesting public web text, code, and images to learn statistical parameters is transformative “non-expressive use” analogous to a student reading library books. Authors, artists, news publishers, and legal scholars counter that industrial scraping to build a commercial product that directly substitutes for the original creators’ market violates the core economic purpose of copyright law (the fourth factor of US fair use and EU Directive 2019/790). Strongest counterargument: The human-reader analogy breaks down on scale and market substitution: a human writer who reads a thousand novels does not emit ten thousand competing articles a second in a living author’s style, which is why major AI labs have quietly signed multimillion-dollar licensing deals with publishers like Axel Springer, the Associated Press, and Reddit while fighting individual creators in court. Nature of the dispute: substantive — decided through statutory interpretation, licensing markets, and judicial rulings on market harm.
General-purpose industrial revolution versus capital-intensive bubble
Venture capitalists and cloud hyperscalers portray generative AI as a general-purpose technology on par with electricity or the printing press. Macroeconomic skeptics (Daron Acemoglu at MIT, Goldman Sachs and Sequoia analysts questioning the “$600 billion revenue gap”) point out that outside coding, customer triage, and marketing copy, high error rates and compute costs have kept measurable productivity gains modest relative to historic data-center spending. Strongest counterargument: Defenders of the long-term thesis note that the 1840s railway mania and 1999 dot-com bubble also saw massive over-investment and write-downs, yet the physical rail and fiber-optic infrastructure laid during the mania permanently restructured the economy over the following two decades. Nature of the dispute: mixed — near-term balance sheets and adoption rates are empirically measurable, while twenty-year productivity forecasts remain speculative bets.
Underappreciated Angle
The most profound cultural consequence of generative AI is the sudden destruction of fluent expression as a costly signal of human thought. For centuries, across schools, universities, courts, and hiring pipelines, a coherent essay, legal brief, or cover letter functioned as a reliable proxy for cognitive effort: because stringing together three thousand grammatically sound words was hard, a polished text proved someone had spent hours thinking through the material. When generative AI drives the marginal cost of polished prose and plausible imagery to zero, the signal collapses overnight. Institutions built around evaluating written artifacts—seminar papers, peer review, public consultations, job applications—are buried under zero-cost synthetic text that takes ten times longer to read than to generate. Stanisław Lem captured this reversal in 1965: once Trurl’s Electronic Bard is switched on, the crisis is not that the machine writes bad poetry, but that it floods the world with effortlessly consummate verse until human poets lose the social space in which their labor mattered. Alongside this signaling collapse sits an ecological feedback loop: filling the digital commons with synthetic outputs narrows future training corpora (model collapse), consuming the very epistemic commons—costly human expression—on which generative AI depends.
One-Sentence Takeaway
Generative AI does not invent new ideas out of nothing; it drives the marginal cost of statistically plausible text, code, and images to zero—and it is that price collapse, rather than machine consciousness, that is destabilizing every human institution built on the assumption that fluent expression requires effort.
Related Concepts Network
How this concept reinforces, constrains, or complements other analytical frameworks in the corpus. View on graph →
-
Transformer reinforces
The Transformer architecture serves as the computational engine for virtually all generative text and code models and increasingly (via diffusion transformers) for image and video synthesis.
-
Large language models (LLMs) complements
Large language models are the flagship text-based class of generative AI, whereas the broader concept also encompasses image, audio, 3D, and video generation.
-
Diffusion models complements
Denoising diffusion models constitute the second major algorithmic family alongside Transformers, powering the 2022 breakthrough in high-resolution image and video synthesis.
-
Foundation models complements
A foundation model names the shared upstream resource, whereas generative AI names the mode of output: the same pretrained model can be used either to classify existing inputs or to generate new artifacts.
-
Model hallucinations constrains
Plausible-sounding fabrications are intrinsic to sampling from a learned probability distribution rather than a superficial bug that can be patched out.
-
Model collapse in tension
Flooding the internet with machine-generated outputs contaminates future training corpora, meaning that the commercial triumph of generative AI threatens to erode its own statistical foundation.
-
AI slop reinforces
Driving the marginal cost of producing text, images, and video toward zero inundates digital public spaces with low-effort, uncurated synthetic filler.
-
Synthetic media reinforces
Synthetic media is the cultural, media-studies, and regulatory term for the artifacts produced by what engineers and investors call generative AI.
Reading Canon & Translation Bridge
Foundational texts, introductions, and critical perspectives—with availability of English and Polish editions.
-
foundational text 2014 · English
Ian J. Goodfellow, Jean Pouget-Abadie, Mehdi Mirza, Bing Xu, David Warde-Farley, Sherjil Ozair, Aaron Courville, Yoshua Bengio, Generative Adversarial Networks
The NIPS 2014 paper that showed how two neural networks pitted against each other in a minimax game can learn to sample realistic novel images from complex distributions, launching the modern deep generative modeling era.
In English: original text written in English
In Polish: no Polish edition
-
foundational text 2017 · English
Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N. Gomez, Łukasz Kaiser, Illia Polosukhin, Attention Is All You Need
Replaced recurrent networks with parallelizable self-attention, enabling sequence models to scale to the whole-internet corpora that made generative text and code viable.
In English: original text written in English
In Polish: no Polish edition
-
foundational text 2010 · English
Tomáš Mikolov, Martin Karafiát, Lukáš Burget, Jan Černocký, Sanjeev Khudanpur, Recurrent neural network based language model
Four pages from Brno University of Technology proving that a neural network predicting the next word from continuous hidden states beats classic n-gram tables—the core task of modern text generation.
In English: original text written in English
In Polish: no Polish edition
-
introduction & synthesis 2022 · English
Robin Rombach, Andreas Blattmann, Dominik Lorenz, Patrick Esser, Björn Ommer, High-Resolution Image Synthesis with Latent Diffusion Models
The CVPR 2022 paper behind Stable Diffusion: demonstrated how moving the denoising diffusion process into a compressed latent space made high-resolution image generation runnable on consumer GPUs.
In English: original text written in English
In Polish: no Polish edition
-
critical perspective 2021 · English
Emily M. Bender, Timnit Gebru, Angelina McMillan-Major, Shmargaret Shmitchell, On the Dangers of Stochastic Parrots: Can Language Models Be Too Big?
The most widely cited critical intervention: challenges environmental externalities, dataset bias, and the category mistake of confusing statistical form generation with communicative understanding.
In English: original text written in English
In Polish: Polish edition not verified
-
introduction & synthesis 2019 · English
Melanie Mitchell, Artificial Intelligence: A Guide for Thinking Humans
A clear-eyed introduction for non-specialists explaining the conceptual gulf between statistical pattern synthesis and human common-sense understanding.
In English: original text written in English
In Polish: Polish edition not verified
-
cross-disciplinary 1965 · Polish
Stanisław Lem, Cyberiada
The story of Trurl's Electronic Bard (“Elektrybałt”) remains the sharpest philosophical thought experiment in literature on what happens to human poets when a machine can generate verse on demand.
In English: “The Cyberiad: Fables for the Cybernetic Age”, Harcourt Brace 1974, trans. Michael Kandel
In Polish: original text written in Polish
Primary-Source Quotes
We provide ample empirical evidence to suggest that connectionist language models are superior to standard n-gram techniques, except their high computational (training) complexity.