AI Architecture #121
Model hallucinations
original term: hallucination (Eng.) · konfabulacje modeli, AI hallucination, zmyślenia modeli
Global-circulation concept — no documented lineage in Central Europe. jump to documentation ↓
Working Definition
A model hallucination is model-generated content that reads fluently and confidently while lacking support either in the input context or in verifiable facts about the world. Technically, researchers distinguish between an intrinsic hallucination, where the output directly contradicts the source document provided to the model, and an extrinsic hallucination, where the output adds claims that the source neither confirms nor refutes. In everyday usage, the term simply means “something a chatbot made up”: a nonexistent academic paper, a bogus judicial precedent, or an invented quotation. Operationally, one property defines the phenomenon: the error is never flagged as an error, because the model has no built-in threshold below which it refuses to answer.
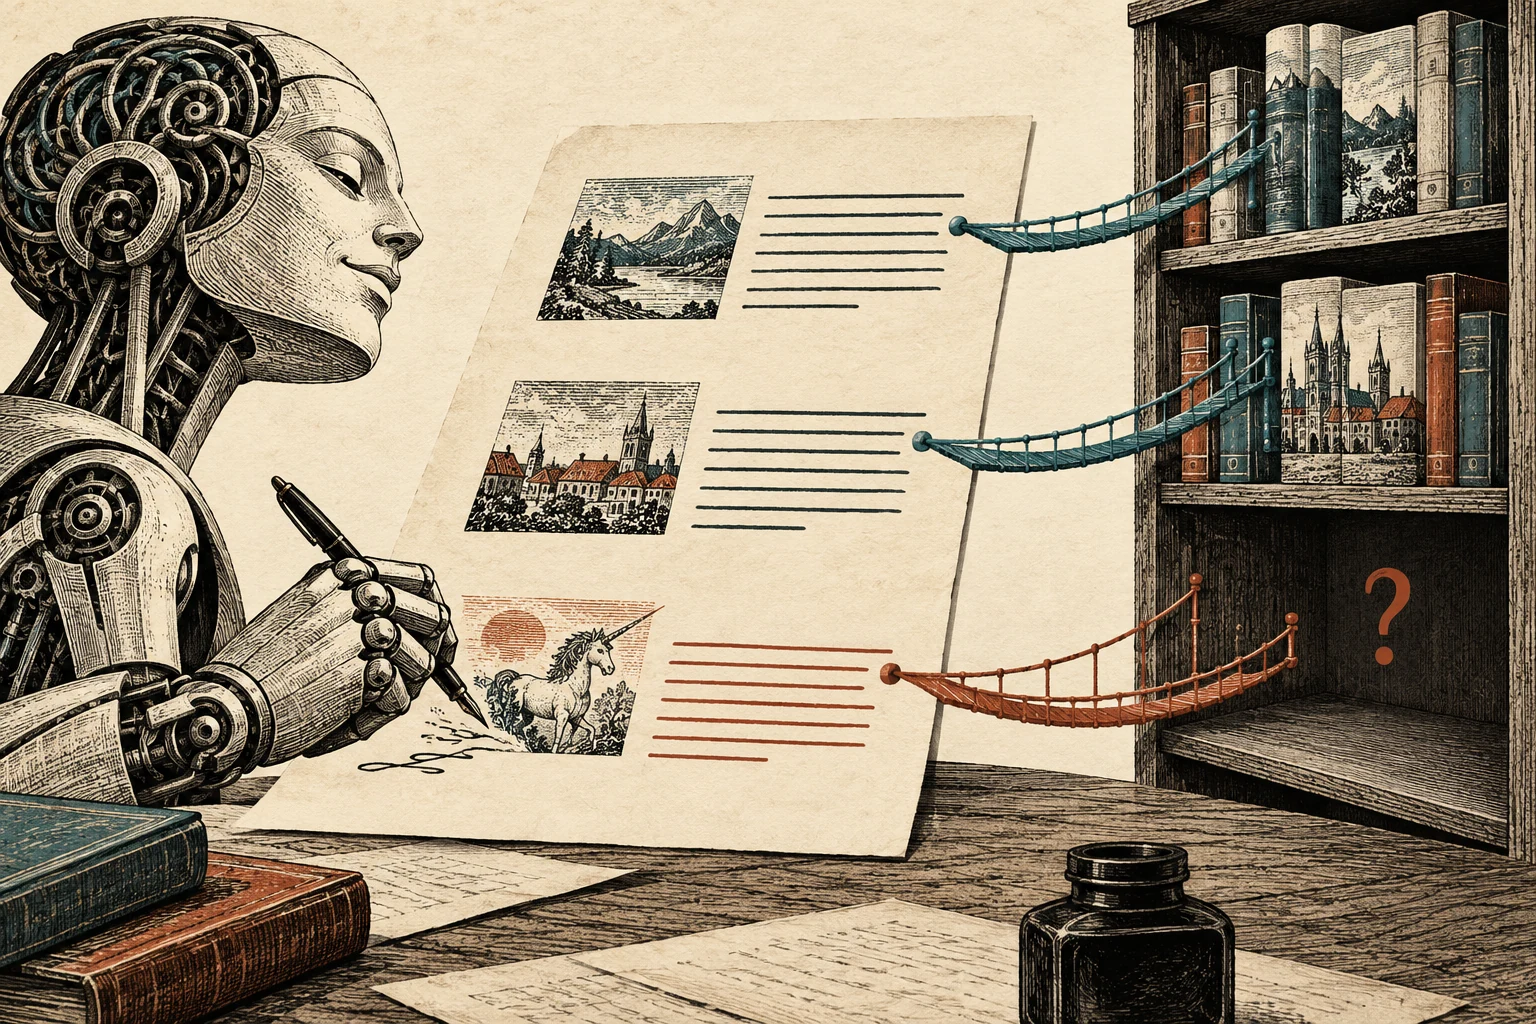
A fluent passage in the output leads to an empty source shelf; a plausible tone does not automatically distinguish grounded claims from fabrication.
AI-assisted illustration · conceptual metaphor View in visual quiz →Genesis and Global Lineage
The word entered machine learning by a circuitous route. In computer vision from the late 1990s onward, “hallucination” meant desirable detail completion, such as reconstructing a high-resolution face from a tiny low-resolution thumbnail (Simon Baker and Takeo Kanade, 1999). In natural language processing, the valence flipped from positive to negative: during the second half of the 2010s, neural machine translation researchers used the term for outputs completely detached from the source sentence, and in 2020 Joshua Maynez and coauthors, studying abstractive summarization, introduced the now-standard distinction between faithfulness to the source document and factual accuracy about the world. Ziwei Ji and colleagues (arXiv 2022; ACM Computing Surveys, 2023) systematized these definitions and metrics just before the term spilled over into mass journalism. The canonical source on our concept list—Emily M. Bender, Timnit Gebru, Angelina McMillan-Major, and Margaret Mitchell’s “On the Dangers of Stochastic Parrots” (2021)—does not analyze hallucinations under that label, but supplies their foundational frame: a language model assembles linguistic forms without access to meaning, while communicative intent and truth value are projected onto the text by human readers. After the launch of ChatGPT in November 2022, general media seized on the term, and Cambridge Dictionary named hallucinate its Word of the Year for 2023. Since then, the concept has lived a double life: as a precise evaluation category inside AI laboratories and as a catch-all popular explanation for every chatbot mistake.
Central European Lineage
We found no documented link between this concept and the intellectual history or historical experience of Central Europe.
We found no documented link between this concept and the intellectual history or historical experience of Central Europe (by our methodology, this means “none found,” not “none exists”; as of October 2026).
Why Now
The phenomenon existed long before ChatGPT, but it became a public crisis only when generative models reached hundreds of millions of users through conversational interfaces lacking any indicator of epistemic uncertainty. In June 2023, Judge P. Kevin Castel of the U.S. District Court for the Southern District of New York fined attorneys $5,000 in Mata v. Avianca for submitting a legal brief citing nonexistent judicial opinions fabricated by ChatGPT; the case became an archetype for dozens of similar incidents across courts, newsrooms, and scientific publishing. In 2024, Sebastian Farquhar and Yarin Gal’s Oxford team published a method in Nature for detecting arbitrary confabulations via semantic entropy, while philosophers Michael Townsen Hicks, James Humphries, and Joe Slater argued that the field should abandon the word “hallucination” altogether in favor of Harry Frankfurt’s concept of “bullshit.” In September 2025, Adam Tauman Kalai, Ofir Nachum, Santosh S. Vempala, and Edwin Zhang shifted the blame from neural architecture to evaluation incentives in “Why Language Models Hallucinate”: models guess because standard benchmarks reward guessing over abstention. The dispute is no longer purely technical; it concerns who bears institutional accountability for confident falsehoods.
Explanatory Power
The concept makes it possible to disentangle three distinct failure modes that everyday talk of “AI making mistakes” collapses into one. First is a knowledge failure: the model never encountered the relevant fact in its training corpus or was trained on noisy data. Second is a faithfulness failure: the model was given an explicit source document in its context window and distorted it anyway—a distinct problem in Retrieval-Augmented Generation (RAG) pipelines, where supplying a verified source does not guarantee a faithful summary. Third is a calibration failure: the model assigns low internal consistency to a claim, yet its decoding and post-training layers produce the same authoritative tone as they do for well-established facts. This three-way distinction has immediate practical consequences. A law firm deploying a drafting assistant must measure citation faithfulness rather than general benchmark accuracy. A newsroom using an LLM to summarize transcripts needs tests for intrinsic hallucinations, because extrinsic fabrications are often easier for editors to spot. And a benchmark designer who scores a blank “I don’t know” at zero—the exact same score as a fabricated answer—actively trains models to gamble, as Kalai and his coauthors demonstrate mathematically.
Axes of Debate
Fixable engineering flaw versus structural feature
AI laboratories and product builders treat hallucination rates as an engineering metric that declines with each model generation thanks to cleaner training data, retrieval grounding, and reinforcement learning. Critics working in the tradition of Bender and Gebru counter that a system trained solely to model the statistical distribution of word forms has no external reality to “check back” against, so reducing the percentage of fabrications does not alter the nature of the mechanism. Strongest counterargument: Kalai and colleagues show that while a baseline level of statistical error on rare facts is mathematically unavoidable, its persistence as confident fabrication in deployed products is an institutional choice: changing evaluation rubrics to penalize wrong guesses more heavily than abstentions teaches models to stay silent when uncertain. Nature of the dispute: mixed — both sides agree on the underlying next-token mechanism, but diverge over whether a non-zero fabrication rate disqualifies a tool from cognitive and professional workflows.
Hallucination, confabulation, or bullshit
Philosophers and cognitive scientists (Hicks, Humphries, and Slater, building on earlier critiques of anthropomorphism by Murray Shanahan) argue that “hallucination” implies a perceiving subject who normally sees the world accurately and occasionally misfires; because a language model perceives nothing, the accurate term is Frankfurtian “bullshit”—speech produced without regard for truth. Proponents of “confabulation” (borrowed from neuropsychology and adopted by Farquhar and Gal) prefer to emphasize how models fill gaps with fluent, ungrounded narratives, much like patients with memory disorders. Strongest counterargument: Philosophically precise labels have zero operational traction in engineering: “bullshit” does not yield a loss function or an evaluation benchmark, whereas “hallucination” has served since 2018 across hundreds of technical papers as the established name for a measurable class of errors. Nature of the dispute: substantive — the choice of metaphor shapes the mental model that users, judges, and regulators bring to the machine, directly affecting trust and legal liability.
Who is liable for confident falsehoods
Courts and professional disciplinary bodies place responsibility on the human operator—the lawyers in Mata v. Avianca were sanctioned for failing to verify citations in the register. Human–computer interaction researchers and AI ethicists point instead to the vendor, who designs the conversational interface to project seamless authority without exposing uncertainty estimates, even when methods for computing semantic uncertainty exist. Strongest counterargument: A model that hedges every single sentence with probability disclaimers quickly becomes unusable, and human operators rapidly succumb to warning fatigue and ignore boilerplate caveats; professional responsibility cannot be offloaded entirely onto interface design. Nature of the dispute: mixed — the legal allocation of liability is a substantive institutional question, but both camps also deploy “hallucination” rhetorically, either to distance the vendor from a “quirk” of the model or to blame the tool for human negligence.
Underappreciated Angle
The least discussed consequence of model hallucinations concerns not the individual user who gets tricked, but the long-term integrity of the documentary record itself. A fabricated citation, date, or biographical detail that slips into a published article, court filing, or encyclopedia entry becomes a real document; that document is scraped into the next web corpus; and the next generation of models learns the fabrication as an attested fact, repeating it with even higher confidence because it now appears across “independent” sources. The problem ceases to be a localized error inside a single neural network and becomes an ecological property of the textual commons, where it grows progressively harder to tell what someone actually verified in an archive from what was merely generated in plausible prose. Projects that require explicit source verification and exact locators—including the knowledge base you are reading—are a direct institutional response to this shift: documentary verification becomes a distinct, mandatory stage of intellectual work once fluency ceases to be a proxy for reliability.
One-Sentence Takeaway
A hallucination is not the moment a language model stops working properly, but the moment it works exactly as designed—only this time without factual backing.
Related Concepts Network
How this concept reinforces, constrains, or complements other analytical frameworks in the corpus. View on graph →
-
Large language models (LLMs) complements
Hallucination is a structural operating mode of a language model, not an externally introduced bug: the very same token-prediction mechanism produces both accurate and fabricated answers.
-
RLHF in tension
Fine-tuning on human ratings rewards confident and fluent answers, which can increase a model’s willingness to guess rather than admit ignorance.
-
RAG (Retrieval-Augmented Generation) constrains
Supplying retrieved documents in context curbs the invention of external facts, but shifts the problem onto faithfulness to the source and does not eliminate intrinsic hallucinations.
-
AI alignment complements
A model that cannot signal uncertainty is difficult to align with user intent regardless of its broader objectives.
-
Epistemic humility reinforces
The debate over hallucinations is at bottom a debate over whether a machine can say “I don’t know” and whether our evaluation systems reward it for doing so.
-
Network epistemology reinforces
Fabricated citations and court rulings enter the documentary circulation and from there feed into the training data of subsequent models.
-
Model collapse complements
Hallucinations published on the web become training data and contribute to the degradation of subsequent generations of models.
-
Explainable AI (XAI) complements
Hallucination-detection methods such as semantic uncertainty measures attempt to probe inside the model’s predictive distribution without opening its weights.
Reading Canon & Translation Bridge
Foundational texts, introductions, and critical perspectives—with availability of English and Polish editions.
-
foundational text 2022 · English
Ziwei Ji, Nayeon Lee, Rita Frieske, Tiezheng Yu, Dan Su, Yan Xu, Etsuko Ishii, Yejin Bang, Andrea Madotto, Pascale Fung i in., Survey of Hallucination in Natural Language Generation
The survey that organized the field before the ChatGPT era: definitions, the distinction between intrinsic and extrinsic hallucinations, metrics, and mitigation methods; journal version in “ACM Computing Surveys” (DOI 10.1145/3571730).
In English: original text written in English
In Polish: no Polish edition
-
foundational text 2020 · English
Joshua Maynez, Shashi Narayan, Bernd Bohnet, Ryan McDonald, On Faithfulness and Factuality in Abstractive Summarization
An ACL 2020 paper on summarization that distinguished faithfulness to the source from factuality and showed that human annotators find fabrications in the summaries of every tested model.
In English: original text written in English
In Polish: no Polish edition
-
introduction & synthesis 2025 · English
Adam Tauman Kalai, Ofir Nachum, Santosh S. Vempala, Edwin Zhang, Why Language Models Hallucinate
A statistical explanation of the phenomenon: hallucinations are ordinary binary classification errors amplified by benchmarks that score guessing higher than admitting uncertainty.
In English: original text written in English
In Polish: no Polish edition
-
critical perspective 2024 · English
Michael Townsen Hicks, James Humphries, Joe Slater, ChatGPT is bullshit
A philosophical critique of the term: model outputs are not hallucinations but Frankfurtian “bullshit,” because the system is structurally indifferent to truth; published in “Ethics and Information Technology.”
In English: original text written in English
In Polish: Polish edition not verified
-
critical perspective 2021 · English
Emily M. Bender, Timnit Gebru, Angelina McMillan-Major, Shmargaret Shmitchell, On the Dangers of Stochastic Parrots: Can Language Models Be Too Big?
The source cited in the concept list: argues that a language model stitches together linguistic forms without access to meaning, while the reader projects sense onto the output—a framework in which fabrication is the rule rather than the exception.
In English: original text written in English
In Polish: Polish edition not verified
-
introduction & synthesis 2024 · English
Sebastian Farquhar, Jannik Kossen, Lorenz Kuhn, Yarin Gal, Detecting hallucinations in large language models using semantic entropy
A “Nature” paper proposing to measure uncertainty at the level of meanings rather than token sequences in order to detect confabulations—fabrications that shift across sampled responses.
In English: original text written in English
In Polish: no Polish edition
-
cross-disciplinary 2005 · English
Harry G. Frankfurt, On Bullshit
The classic essay on speech indifferent to truth—which does not lie so much as not care—providing the core conceptual tool for debating whether “hallucination” is the right word.
In English: original text written in English
In Polish: Polish edition not verified
Primary-Source Quotes
language models are optimized to be good test-takers
highly prone to hallucinate content that is unfaithful to the input document