AI Architecture #130
Model collapse
original term: model collapse (Eng.) · zapaść modelu, kolaps modelu, model autophagy disorder (MAD)
Global-circulation concept — no documented lineage in Central Europe. jump to documentation ↓
Working Definition
Model collapse is a degenerative process affecting successive generations of generative models when each new generation is trained on data produced by its predecessors: first, rare events in the tails of the probability distribution vanish (early model collapse), and eventually the model loses variance altogether, conflates distinct modes, and converges toward a narrow, distorted caricature of reality (late model collapse). The mechanism requires no software bug or architectural flaw; finite sampling variance, functional approximation error, and iterative resampling suffice to make errors compound across generations like a random walk with absorbing boundaries. In rigorous technical usage, the term describes a specific statistical property of recursively fitted estimators; in popular commentary, it serves as shorthand for the broader fear that “AI eating its own exhaust will go mad.” Keeping the two registers distinct is essential, because empirical outcomes depend heavily on whether synthetic outputs completely replace human training data or accumulate alongside it.
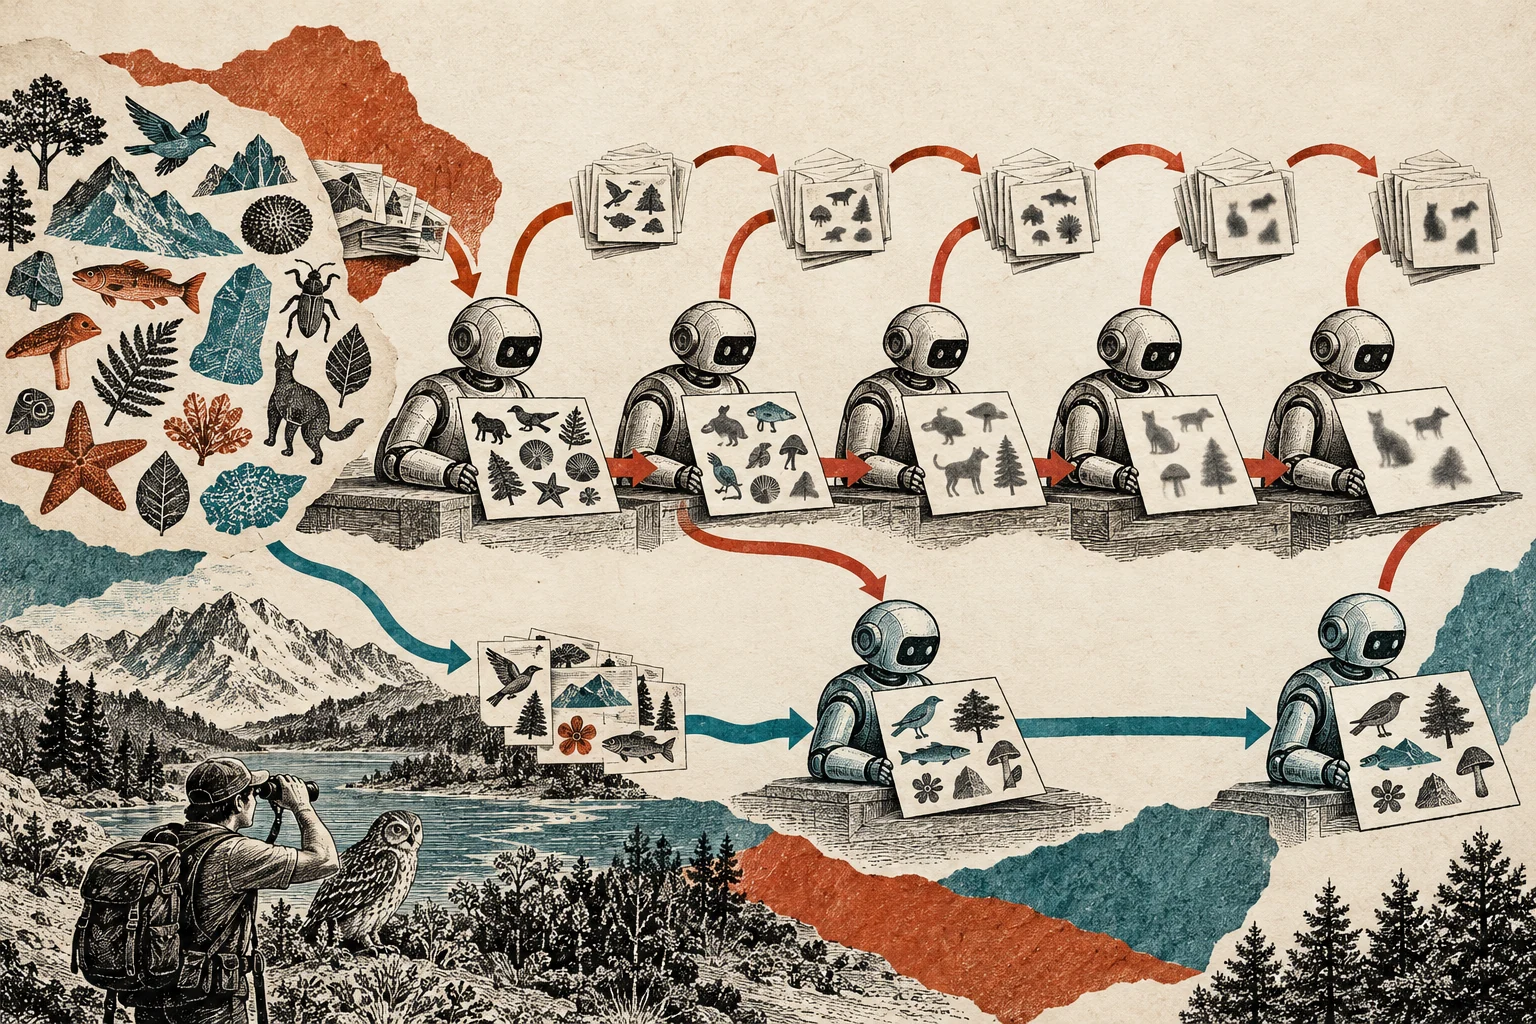
Successive generations trained on their own outputs lose rare variants, though fresh real data and careful curation can alter the trajectory.
AI-assisted illustration · conceptual metaphor View in visual quiz →Genesis and Global Lineage
The term was coined by Ilia Shumailov, Zakhar Shumaylov, Yiren Zhao, Yarin Gal, Nicolas Papernot, and Ross Anderson in their May 27, 2023 arXiv preprint The Curse of Recursion: Training on Generated Data Makes Models Forget, written across Cambridge, Oxford, and Toronto by researchers rooted in machine-learning security and Bayesian uncertainty rather than commercial model scaling. When the peer-reviewed version appeared on the cover of Nature on July 24, 2024 (AI models collapse when trained on recursively generated data), the concept entered mainstream policy and media vocabulary worldwide. Independently, in July 2023, Richard Baraniuk’s group at Rice University analyzed the same dynamics in visual diffusion models and GANs under the name Model Autophagy Disorder (MAD), by analogy to mad cow disease, while technology critic Jathan Sadowski popularized the memorable moniker Habsburg AI, likening recursive synthetic training to dynastic inbreeding. Mathematically, the lineage descends from classical statistics—finite-sample estimation bias, genetic drift in population biology, and the progressive truncation of heavy tails under repeated kernel smoothing—combined with cybersecurity research on training-data poisoning. Almost immediately, popular journalism co-opted the paper as a prophecy of the imminent death of large language models, stretching a conditional mathematical theorem into an unconditional historical forecast.
Central European Lineage
We found no documented link between this concept and the intellectual history or historical experience of Central Europe.
We found no documented link between this concept and the intellectual history or historical experience of Central Europe (by our methodology, this means “none found,” not “none exists”; as of October 2026).
Why Now
Three developments between 2022 and 2026 turned recursive training from a theoretical curiosity into an urgent industry bottleneck. First, following the release of ChatGPT (November 2022) and Stable Diffusion (August 2022), machine-generated text, translations, product reviews, and images began flooding the public web so rapidly that every new snapshot of Common Crawl contains a higher fraction of synthetic tokens; AI researchers began comparing pre-2022 web archives to low-background steel—metal forged before the 1945 Trinity nuclear test, prized for Geiger counters because it is uncontaminated by atmospheric fallout. Second, the July 2024 Nature publication gave regulators and copyright holders a scientific argument for mandatory content watermarking, data provenance registries, and licensing deals for verified human archives. Third, at the exact same time, frontier AI laboratories expanded their deliberate reliance on synthetic training data—using teacher-model distillation, self-play, and synthetic math and coding traces—yielding empirical capability gains that appeared to contradict naive doom scenarios. In April 2024, Matthias Gerstgrasser, David Donoho, Sanmi Koyejo, and coauthors (including Polish researcher Tomasz Korbak) demonstrated in Is Model Collapse Inevitable? that when synthetic generations are accumulated on top of persistent real data rather than replacing it, test error remains bounded; simultaneously, Elvis Dohmatob, Julia Kempe, and colleagues showed that synthetic contamination manifests not as an overnight explosion of gibberish, but as a degradation of neural scaling laws. The concept became indispensable precisely because it names the central statistical constraint governing AI data economics after 2025.
Explanatory Power
The concept makes clear that the epistemic quality of a model is an ecological property of the information commons rather than an isolated feature of a neural architecture. First, Shumailov et al.’s distinction between early and late collapse explains a deceptive phenomenon in everyday model evaluation: in early collapse, a model quietly drops low-probability tail events while its average performance around the central mode actually improves (because sampling with temperature < 1 or preference tuning trims away noisy outliers). This explains why successive generations of chatbots can sound smoother, more polished, and more uniform in prose style while becoming progressively worse at handling regional dialects, low-resource languages, minority cultural references, and atypical clinical presentations. Second, as Ross Anderson emphasized, the model-collapse framework explains the intense strategic race among tech giants to lock up proprietary streams of verified human interaction and pre-2022 archives (licensing Reddit, Stack Overflow, news publishers, and digitized books): clean human data becomes a non-renewable strategic reserve conferring a durable first-mover advantage. Third, it provides a unified framework for analyzing why synthetic data works brilliantly in formal domains (like AlphaZero chess, theorem proving, or compilable code, where an external ground-truth verifier prunes bad samples) while degrading open-ended cultural and factual domains where no oracle exists to stop errors from compounding.
Axes of Debate
Data replacement versus data accumulation
Shumailov and colleagues model a generational Markov process in which generation n is trained largely or entirely on samples drawn from generation n-1. Critics led by Gerstgrasser, Schaeffer, Donoho, and Koyejo (Stanford and collaborators, 2024) argue that this replacement assumption does not match industrial practice: laboratories never delete their original pre-2022 human corpus when adding new web scrapes or synthetic mixes, and under data accumulation, theoretical error stays bounded rather than diverging. Strongest counterargument: Accumulation bounds hold only so long as the clean human anchors retain non-negligible weight relative to the incoming synthetic flood; if the volume of machine-generated web content grows orders of magnitude faster than human writing—or if smaller developers train from scratch on newly scraped web snapshots without access to proprietary historical archives—the effective ratio approaches the replacement regime anyway. Nature of the dispute: substantive — both camps agree on the underlying mathematics of both regimes and debate which formal model accurately represents the evolving political economy of web corpora.
Catastrophic breakdown versus degraded scaling laws
Popular technology commentary often portrays model collapse as an impending cliff where chatbots suddenly start outputting unintelligible word salad. Theorists such as Elvis Dohmatob, Yunzhen Feng, and Julia Kempe (Meta FAIR and NYU, 2024) reframe collapse in high-dimensional regression as a shift in the exponent of neural scaling laws: models do not necessarily disintegrate, but the rate at which test error falls with additional data and compute flattens out, creating a “capability plateau” on tail tasks. Strongest counterargument: In an industry whose trillion-dollar capital expenditure is predicated on predictable power-law returns from scaling compute clusters, a flattening of the scaling exponent is economically indistinguishable from a crisis, even if the model continues to speak grammatically correct English. Nature of the dispute: mixed — the mathematical characterization of scaling exponents is purely substantive, while public framing oscillates rhetorically between apocalyptic hyperbole and corporate reassurance.
Unfiltered web scraping versus verifier-guided synthetic curation
Engineers building frontier reasoning models argue that “model collapse” is merely an artifact of naive, uncurated sampling: when synthetic generations are filtered by formal verifiers (unit tests, math solvers, reward models) or used for targeted knowledge distillation, synthetic data actively improves capability beyond the human training baseline. Strongest counterargument: External ground-truth verifiers exist only for formal, closed-world tasks like coding and mathematics; for history, journalism, law, medical diagnosis, and natural linguistic variation, there is no automated compiler for truth, and using another neural network as the judge simply moves the recursive bias one level up into the reward model. Nature of the dispute: substantive — it turns on which domains possess a cheap, non-neural verification oracle and which ones do not.
Underappreciated Angle
The most politically consequential feature of model collapse is the radical asymmetry of who disappears first. Because recursive estimation erodes the tails of a probability distribution long before it disturbs the center, early model collapse is invisible on mainstream English-language leaderboards while already devastating the margins. In a global corpus, the “tails” are not random noise: they are smaller national and minority languages (from Kashubian and Upper Silesian to Slovak legal terminology or regional administrative procedures), minority demographic groups, rare genetic disorders, and heterodox intellectual traditions. A model undergoing early collapse can simultaneously achieve higher human-preference scores on standard American business prose and completely lose its grip on Central European historical nuance or non-standard syntax—converting statistical tail truncation directly into cultural homogenization. A second, rarely examined feedback loop runs in the opposite direction—from models back into human writers. As millions of students, journalists, officials, and programmers draft and edit their texts through LLM autocomplete, human linguistic output itself begins converging toward the high-probability modes of the model’s distribution (measurable in the sudden spike of favored LLM vocabulary and triad sentence structures in academic papers after 2023). Model collapse is therefore not just a closed loop inside data centers; it is a two-way ecological coupling in which human culture and statistical models recursively trim each other’s variance.
One-Sentence Takeaway
A generative model does not collapse because it runs out of data, but because it begins learning from its own echo—and what vanishes first in that echo is everything rare, local, and outside the average.
Related Concepts Network
How this concept reinforces, constrains, or complements other analytical frameworks in the corpus. View on graph →
-
Synthetic data in tension
Synthetic data is both the trigger of model collapse (when it uncritically replaces human data) and a proposed remedy (when filtered by verifiers and accumulated alongside real data), making the debate over collapse a debate over the conditions of synthetic training.
-
AI slop reinforces
Mass-produced, low-cost generative content floods the open web and steadily increases the proportion of synthetic artifacts in future web-scraped training corpora.
-
Dead internet theory complements
Model collapse represents the statistical and machine-learning counterpart to the cultural scenario in which the public internet is populated primarily by bots interacting with bots.
-
Scaling laws constrains
Dohmatob and coauthors show that synthetic contamination alters the exponents of neural scaling laws, causing additional compute and data volume to yield diminishing returns.
-
Data provenance reinforces
Without verifiable metadata recording where a text originated and whether a human wrote it, laboratories can neither measure the extent of corpus contamination nor filter out recursive outputs.
-
Feedback loops reinforces
Model collapse is a textbook positive feedback loop in statistical estimation: the output of generation n becomes the training input of generation n+1, compounding sampling and approximation errors at every step.
-
Goodhart’s law complements
Early-stage model collapse can actually improve aggregate benchmark scores around the mode even as the model silently loses rare tail behaviors—a classic divergence between metric and reality.
Reading Canon & Translation Bridge
Foundational texts, introductions, and critical perspectives—with availability of English and Polish editions.
-
foundational text 2024 · English
Ilia Shumailov, Zakhar Shumaylov, Yiren Zhao, Nicolas Papernot, Ross Anderson, Yarin Gal, AI models collapse when trained on recursively generated data
The canonical peer-reviewed formulation in “Nature” (vol. 631, pp. 755–759), establishing the definition, the distinction between early and late collapse, and the decomposition into statistical approximation, functional expressivity, and finite-sampling errors.
In English: original text written in English
In Polish: no Polish edition
-
foundational text 2023 · English
Ilia Shumailov, Zakhar Shumaylov, Yiren Zhao, Yarin Gal, Nicolas Papernot, Ross Anderson, The Curse of Recursion: Training on Generated Data Makes Models Forget
The May 2023 arXiv preprint where the term “model collapse” first appeared, containing fuller mathematical derivations for Gaussian mixtures, variational autoencoders, and language models.
In English: original text written in English
In Polish: no Polish edition
-
foundational text 2023 · English
Sina Alemohammad, Josue Casco-Rodriguez, Lorenzo Luzi, Ahmed Imtiaz Humayun, Hossein Babaei, Daniel LeJeune, Ali Siahkoohi, Richard G. Baraniuk, Self-Consuming Generative Models Go MAD
A parallel formulation for image diffusion models and GANs (July 2023), coining “Model Autophagy Disorder” (MAD) and distinguishing precision loss (image quality) from recall loss (diversity).
In English: original text written in English
In Polish: no Polish edition
-
critical perspective 2024 · English
Matthias Gerstgrasser, Rylan Schaeffer, Apratim Dey, Rafael Rafailov, Henry Sleight, John Hughes, Tomasz Korbak, Rajashree Agrawal, Dhruv Pai, Andrey Gromov, Daniel A. Roberts, Diyi Yang, David L. Donoho, Sanmi Koyejo, Is Model Collapse Inevitable? Breaking the Curse of Recursion by Accumulating Real and Synthetic Data
The most widely cited rebuttal: demonstrates theoretically and empirically that when synthetic data is accumulated alongside original human data rather than replacing it, test error remains bounded and catastrophic collapse does not occur.
In English: original text written in English
In Polish: no Polish edition
-
critical perspective 2024 · English
Elvis Dohmatob, Yunzhen Feng, Pu Yang, Francois Charton, Julia Kempe, A Tale of Tails: Model Collapse as a Change of Scaling Laws
Reframes the phenomenon mathematically: rather than an abrupt total breakdown, training on synthetic data alters the exponents of neural scaling laws, flattening the gains from larger datasets and erasing tail skills.
In English: original text written in English
In Polish: no Polish edition
-
introduction & synthesis 2023 · English
Ross Anderson, Will GPT models choke on their own exhaust?
A June 2023 post on the Light Blue Touchpaper blog by coauthor Ross Anderson, translating the preprint for a broader audience and highlighting the strategic “first-mover advantage” of firms that scraped the pre-2022 human web.
In English: original text written in English
In Polish: no Polish edition
-
cross-disciplinary 1981 · French
Jean Baudrillard, Simulacres et simulation
The philosophical precursor on copies of copies detached from any original referent; useful for contrasting a precise statistical loss of distribution tails with cultural diagnoses of hyperreality.
In English: English edition not verified
In Polish: “Symulakry i symulacja”, Sic! 2005, trans. Sławomir Królak
Primary-Source Quotes
Model Collapse is a degenerative process affecting generations of learned generative models, where generated data end up polluting the training set of the next generation of models; being trained on polluted data, they then mis-perceive reality.