AI Architecture #134
Explainable AI (XAI)
original term: explainable artificial intelligence (XAI) (Eng.) · wyjaśnialna sztuczna inteligencja, interpretowalność modeli, explainable AI
Central European lineage: 2 threads (author from the region, historical experience) · 2015–2024 · jump to documentation ↓
Working Definition
Explainable AI (XAI) is the capacity of a machine learning system—or of an accompanying diagnostic procedure—to provide a human recipient with intelligible reasons for a specific prediction or an account of its internal decision logic that the recipient can verify and act upon: whether to calibrate trust, debug a failure, contest an unfair outcome, or change their own future situation. Technically, the field divides into two fundamentally different strategies: designing intrinsically interpretable models whose structure can be inspected directly (sparse rule lists, generalized additive models, shallow decision trees) versus generating post-hoc explanations for opaque “black-box” models (local feature attributions like LIME and SHAP, saliency maps, or counterfactual explanations showing what input change would flip the output). While everyday marketing treats “explainable AI” as a single property meaning “an AI that tells you why,” rigorous scholarship treats it as a family of distinct methods serving often incompatible goals: engineering diagnostics, scientific discovery, regulatory auditability, and individual legal recourse.
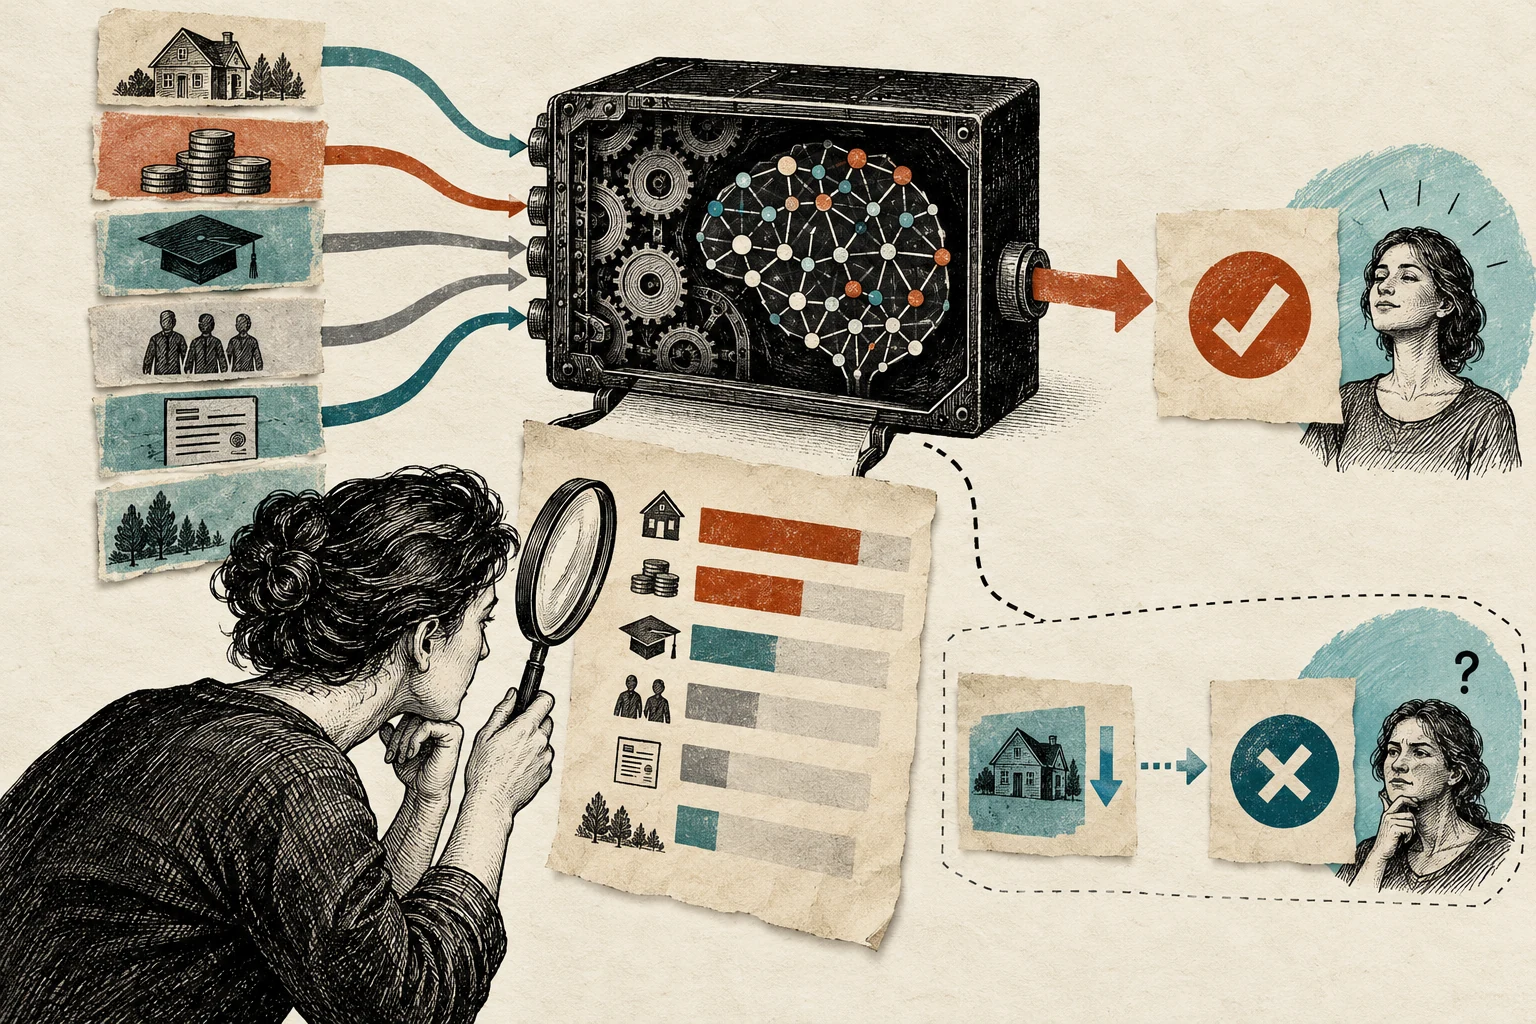
An explanation links the output to salient input features and counterfactual changes, offering a useful approximation rather than a complete view of every internal operation.
AI-assisted illustration · conceptual metaphor View in visual quiz →Genesis and Global Lineage
The demand that a computer program justify its conclusions goes back to 1970s symbolic expert systems (such as MYCIN), which printed traces of IF–THEN rules fired during a consultation. The modern XAI wave erupted after 2012, when deep neural networks and ensemble models outperformed transparent linear models even as opaque systems were deployed in credit scoring, bail, and medicine. In 2015, the U.S. Defense Advanced Research Projects Agency (DARPA) formulated its Explainable Artificial Intelligence (XAI) program under David Gunning (launched 2017; summarized by Gunning and David W. Aha in AI Magazine, 2019), popularizing the acronym XAI. Simultaneously, the ML community built the model-agnostic toolkit: Marco Tulio Ribeiro, Sameer Singh, and Carlos Guestrin introduced LIME in 2016, Scott Lundberg and Su-In Lee introduced SHAP in 2017, and essays by Zachary Lipton (2016) and Finale Doshi-Velez and Been Kim (2017) clarified what interpretability measures. A third, legal lineage crystallized in Europe around the GDPR (2016/2018), where debate over whether Article 22 created a “right to explanation” led Sandra Wachter, Brent Mittelstadt, and Chris Russell (2017/2018) to formulate counterfactual explanations. Since then, XAI has both matured into mechanistic interpretability (reverse-engineering neural circuits inside LLMs) and suffered commercial dilution wherever a bar chart of SHAP values is sold as algorithmic accountability.
Central European Lineage
Central Europe contributed to explainable AI through legal-philosophical theory from Vienna, statutory experimentation in Warsaw, and statistical software engineering. First, counterfactual explanations were spearheaded by Sandra Wachter, who studied law at the University of Vienna, served in the Austrian Federal Ministry of Health, and earned her Viennese doctorate in 2015 before joining the Oxford Internet Institute. In Counterfactual Explanations without Opening the Black Box (2017/2018, with Brent Mittelstadt and Chris Russell), her continental administrative-law perspective shaped the method’s core design: instead of summarizing millions of neural weights, the system states the minimal change to input variables that would reverse an adverse decision (“your loan would have been approved if your annual income were €500 higher”), enabling the citizen to contest a mistake or change future outcomes. Second, Poland enacted a pioneering statutory experiment in 2019 (Act of February 21, 2019, Dziennik Ustaw 2019 item 730): following advocacy by the Warsaw-based Panoptykon Foundation (Fundacja Panoptykon), Parliament added Article 70a to the Polish Banking Law (Prawo bankowe), obliging banks to give rejected loan applicants a written explanation of the specific factors and personal data that shaped their credit score even when a human clerk participated in the final sign-off—closing the GDPR Article 22 “solely automated” loophole five years before Article 86 of the 2024 EU AI Act. Third, Warsaw University of Technology (Politechnika Warszawska) professor Przemysław Biecek created the open-source DALEX ecosystem and coauthored Explanatory Model Analysis (2021).
Documented regional lineage · Links: 2. Compiled: October 2026.
-
author from the region 2 years
Central European Source: Sandra Wachter, “Studia prawnicze na Uniwersytecie Wiedeńskim, praca w austriackim Federalnym Ministerstwie Zdrowia, doktorat w Wiedniu”; Vienna, Austria, 2015
Global Circulation: counterfactual explanations as an operational form of the right to explanation — Sandra Wachter, Brent Mittelstadt, Chris Russell, 2017
-
historical experience 5 years
Central European Source: Ustawa z dnia 21 lutego 2019 r. o zmianie niektórych ustaw w związku z zapewnieniem stosowania RODO (Dz.U. 2019 poz. 730), art. 70a Prawa bankowego — Nowelizacja Prawa bankowego — art. 70a (prawo do wyjaśnienia oceny zdolności kredytowej); Warsaw, Poland, 2019
Global Circulation: statutory right to explanation of algorithmic decisions (GDPR Art. 22; EU AI Act Art. 86) — Unia Europejska, 2024
author from the region
2 yearsSandra Wachter, “Studia prawnicze na Uniwersytecie Wiedeńskim, praca w austriackim Federalnym Ministerstwie Zdrowia, doktorat w Wiedniu”
2015 · Vienna, Austria
counterfactual explanations as an operational form of the right to explanation
2017 · Sandra Wachter, Brent Mittelstadt, Chris Russell
- Claim & Connection
- Sandra Wachter, a legal scholar educated at the Faculty of Law of the University of Vienna (where she also completed her doctorate in 2015) and formerly a legal policy officer at the Austrian Federal Ministry of Health, is the lead author of “Counterfactual Explanations without Opening the Black Box” (arXiv preprint November 2017; published in the "Harvard Journal of Law & Technology" in 2018). The paper defined a counterfactual explanation as the smallest change to input features that would alter an automated decision to a desired outcome, establishing one of the canonical frameworks in XAI and European GDPR scholarship. Her Central European legal and administrative training explains why the method bypasses the internal mechanics of the neural network to measure an explanation by its actionable utility for the citizen contesting a decision.
- Source Documentation
-
- biographical record Oxford Internet Institute, profil „Sandra Wachter”; paragraphs on education (University of Oxford and Law Faculty of the University of Vienna), prior service at the Austrian Ministry of Health, and work on Counterfactual Explanations. oii.ox.ac.uk ↗
- biographical record Wikipedia (en), hasło „Sandra Wachter”; education and career section: legal studies in Vienna, LL.M. 2009, doctorate 2015, legal officer at the Austrian Federal Ministry of Health. en.wikipedia.org ↗
- primary source Sandra Wachter, Brent Mittelstadt, Chris Russell, „Counterfactual Explanations without Opening the Black Box: Automated Decisions and the GDPR”, Harvard Journal of Law & Technology, Vol. 31, No. 2, 2018; arXiv:1711.00399 (v1: 1 XI 2017); abstract: definition of counterfactual explanations and the three aims of explanation (inform, contest, act). arxiv.org ↗
- Historical Context
- Wachter’s Viennese legal formation (doctorate 2015) and work at the Austrian Ministry of Health are confirmed across institutional profiles; the 2017 preprint (published 2018) followed her earlier widely cited 2016/2017 paper with Mittelstadt and Floridi questioning whether the GDPR text itself mandated ex-post explanations.
historical experience
5 yearsUstawa z dnia 21 lutego 2019 r. o zmianie niektórych ustaw w związku z zapewnieniem stosowania RODO (Dz.U. 2019 poz. 730), art. 70a Prawa bankowego — Nowelizacja Prawa bankowego — art. 70a (prawo do wyjaśnienia oceny zdolności kredytowej)
2019 · Warsaw, Poland
statutory right to explanation of algorithmic decisions (GDPR Art. 22; EU AI Act Art. 86)
2024 · Unia Europejska
- Claim & Connection
- Poland’s 2019 amendment to the Banking Law (Article 70a, enacted via the GDPR implementation act Dz.U. 2019 item 730) granted loan applicants a statutory right to receive a written explanation of their creditworthiness assessment detailing the specific factors—including personal data—that influenced the score, regardless of whether the decision was made solely by an algorithm or with human involvement. Championed by the Warsaw-based Panoptykon Foundation, the provision went significantly further than GDPR Article 22 (which restricts safeguards to solely automated decisions) and anticipated by five years the general right to an explanation of high-risk AI decisions enacted in Article 86 of the 2024 EU AI Act.
- Source Documentation
-
- scholarly study EDRi / Panoptykon, „Poland: Banks obliged to explain their credit decisions”, 19 VI 2019; paragraphs on the scope of the right (specific factors including personal data), its applicability regardless of full automation, and how it exceeds GDPR baseline requirements. edri.org ↗
- scholarly study Lege Artis, „Bank musi wyjaśnić przesłanki oceny scoringowej kredytobiorcy (art. 70a pr. bank.)”, 25 IV 2019; text of Article 70a(1)–(2); reference to statute Dz.U. 2019 item 730 and the advocacy role of the Panoptykon Foundation. czasopismo.legeartis.org ↗
- primary source Ustawa z dnia 21 lutego 2019 r. o zmianie niektórych ustaw w związku z zapewnieniem stosowania rozporządzenia (UE) 2016/679, Dz.U. 2019 poz. 730 (tekst ogłoszony, ELI); Article 46 point 4: insertion of Article 70a(1)–(4) into the Banking Law; Article 113: corresponding reference in the Consumer Credit Act. api.sejm.gov.pl ↗
- primary source Regulation (EU) 2024/1689 (AI Act), art. 86 „Right to Explanation of Individual Decision-Making”; paragraphs 1–3; applicable from August 2, 2026 (Article 113). artificialintelligenceact.eu ↗
- Historical Context
- Confirmed directly in the official journal of laws (Dz.U. 2019 item 730, promulgated April 19, 2019, in force May 4, 2019) and European digital-rights analyses.
Why Now
Three developments between 2018 and 2026 turned explainability into a contested legal and safety requirement. First, European law closed the ambiguity left by the GDPR: Article 86 of the EU AI Act (Regulation 2024/1689, applicable August 2026) grants anyone affected by a high-risk AI decision the right to obtain “clear and meaningful explanations of the role of the AI system in the decision-making procedure and the main elements of the decision taken.” Second, public-sector algorithmic scandals—the Dutch childcare benefits affair (toeslagenaffaire), which brought down the cabinet in 2021, and Poland’s constitutional invalidation of opaque unemployment profiling in 2018—proved that unexplainable public-sector scores violate the rule of law. Third, large language models after 2022 created a new paradox: a model can produce a fluent step-by-step justification (Chain-of-Thought), yet studies (Miles Turpin et al., 2023) proved these verbal rationales are often unfaithful post-hoc confabulations hiding demographic bias or prompt cues. This forced frontier AI labs (led by Chris Olah’s team at Anthropic) to invest in mechanistic interpretability, using sparse autoencoders to map internal activation features rather than trusting what a chatbot claims about its reasoning.
Explanatory Power
The concept pulls apart three properties that everyday talk of “transparency” conflates: faithfulness (does the explanation reflect the actual computation inside the model?), intelligibility (can a doctor, loan applicant, or judge understand it?), and actionability (can the recipient use it to catch an error, appeal, or improve their standing?). First, in engineering diagnostics, Ribeiro et al. (2016) showed a classifier distinguishing wolves from huskies where LIME saliency maps revealed the network was looking only at snow in the background—shortcut learning invisible in accuracy scores. Second, in consumer finance, handing a rejected borrower fifty SHAP values is mathematically faithful but useless to the citizen, whereas a counterfactual explanation reveals whether the rejection rested on an outdated credit-bureau entry. Third, in conversational AI, a chatbot’s chain of thought is maximally intelligible and persuasive to a reader, yet may have low faithfulness to the underlying Transformer circuits—explaining why “asking the model to explain itself” is no substitute for external auditing.
Axes of Debate
Post-hoc explanations of black boxes versus intrinsically interpretable models
Duke computer scientist Cynthia Rudin (Stop Explaining Black Box Machine Learning Models for High Stakes Decisions, 2019) argues that in high-stakes tabular decisions—sentencing, credit, clinical scoring—post-hoc approximations (LIME, SHAP) are inherently flawed: if a post-hoc explanation were 100% faithful everywhere, it would be the black box, so simplified approximations necessarily lie in some regions. Because sparse rule lists and generalized additive models achieve comparable accuracy on tabular data, Rudin argues deploying black boxes there is inexcusable. Strongest counterargument: Proponents of post-hoc XAI and mechanistic interpretability reply that while Rudin’s thesis holds for tabular spreadsheets, in raw vision, acoustics, protein folding, and natural language, deep neural networks vastly outperform sparse rule lists, making post-hoc attribution and circuit probing indispensable. Nature of the dispute: substantive — turning on the empirical accuracy gap between glass-box and black-box models across data modalities.
Explanations built for engineers versus explanations built for affected citizens
Cognitive scientist Tim Miller (2019) and HCI researchers note that most XAI tools were built by ML engineers for ML engineers, outputting feature-importance rankings or heatmaps, whereas social-science research shows humans understand explanations contrastively (“why was my application rejected instead of approved?”). Strongest counterargument: User studies (Harmanpreet Kaur, Himabindu Lakkaraju, et al., 2019–2024) revealed that clean visual charts and fluent counterfactuals systematically induce overtrust (automation bias), persuading users and data scientists to approve erroneous predictions; moreover, Dylan Slack et al. (2020) proved that LIME and SHAP can be adversarially “scaffolded” so a racist classifier outputs innocuous attributions during an audit. Nature of the dispute: mixed — designing explanations for human cognition is a substantive HCI problem, but “user-friendly explainability” can also serve as persuasive theater (explainability-washing).
Does a legally enforceable “right to explanation” work in practice?
Digital-rights advocates (Panoptykon Foundation, EDRi) and drafters of EU AI Act Article 86 argue that an individualized right to explanation is essential to enable legal appeals against automated decisions. Legal skeptics (Lilian Edwards, Michael Veale) warn that individual rights place an unrealistic burden on lone citizens to audit complex systems after the fact, whereas systemic safety requires ex-ante institutional audits. Strongest counterargument: Poland’s experience with Banking Law Article 70a shows the choice is not binary: while an explanation rarely turns a borrower into a data scientist, the statutory duty to produce a written list of scoring factors forces banks to clean up arbitrary variables before deployment—though vague statutory wording still invites boilerplate responses unless regulators enforce specificity. Nature of the dispute: substantive — concerning the institutional effectiveness of individual transparency rights versus systemic ex-ante regulation.
Underappreciated Angle
Explainable AI is usually framed as translating linear algebra into charts, when in reality it is a problem of institutional power and contestability. If an algorithm denies your business loan or flags your tax return, and the XAI module prints a faithful SHAP plot showing “ZIP code contributed -0.42,” you are still powerless if the institution provides no legal procedure to challenge those features or correct the underlying record. Conversely, Poland’s Article 70a and Wachter’s counterfactual framework matter because they alter legal symmetry: they force the decision-maker to commit on paper to which facts drove the outcome, creating a record contestable in court. Yet statutory mandates also create a market for ornamental explanations generated to check a box. The decisive test of XAI is therefore not “can the algorithm generate a rationale?”, but “does the institution pay a penalty if the rationale is unfaithful or based on an illegitimate factor?”
One-Sentence Takeaway
An explanation that the recipient cannot verify against reality or use to contest the decision-maker’s outcome is not an explanation at all, but an automated courtesy note.
Related Concepts Network
How this concept reinforces, constrains, or complements other analytical frameworks in the corpus. View on graph →
-
Algorithmic bias complements
Explaining a decision is a primary tool for discovering that a model relies on discriminatory proxies, though post-hoc approximations can also be manipulated to mask bias behind a plausible-sounding rationale.
-
AI alignment complements
Without insight into why a model produces a given behavior, evaluators cannot tell genuine goal alignment apart from deceptive or superficial compliance; mechanistic interpretability is the verification arm of alignment.
-
Model hallucinations reinforces
Chain-of-thought rationales generated by large language models can themselves be hallucinations: fluent post-hoc justifications that do not reflect the internal circuit computations that produced the answer.
-
Red teaming complements
Red teaming probes a model from the outside through adversarial inputs, whereas explainability probes it from the inside through attribution and circuit analysis; the two are complementary audit paradigms.
-
Goodhart’s law in tension
Once “providing an explanation” becomes a statutory compliance checkbox, organizations optimize for generating plausible-looking charts rather than genuine human comprehension.
-
Information asymmetry reinforces
An opaque algorithmic decision represents an extreme information asymmetry between the scoring institution and the scored citizen; the legal right to explanation is an attempt to rebalance that power relation.
-
Epistemic humility complements
A trustworthy explanation should communicate the model’s own epistemic uncertainty and boundary of validity—something standard feature-importance plots rarely display.
Reading Canon & Translation Bridge
Foundational texts, introductions, and critical perspectives—with availability of English and Polish editions.
-
foundational text 2019 · English
David Gunning, David W. Aha, DARPA's Explainable Artificial Intelligence (XAI) Program
Written by the managers of the DARPA program (“AI Magazine” 40(2), pp. 44–58) that popularized the acronym XAI and structured the field around three pillars: deep explainable models, explanation interfaces, and the cognitive psychology of explanation.
In English: original text written in English
In Polish: no Polish edition
-
foundational text 2016 · English
Marco Tulio Ribeiro, Sameer Singh, Carlos Guestrin, „Why Should I Trust You?”: Explaining the Predictions of Any Classifier
The KDD 2016 paper introducing LIME (Local Interpretable Model-agnostic Explanations): approximates any black-box classifier locally around a single prediction using a sparse linear model.
In English: original text written in English
In Polish: no Polish edition
-
foundational text 2018 · English
Sandra Wachter, Brent Mittelstadt, Chris Russell, Counterfactual Explanations without Opening the Black Box: Automated Decisions and the GDPR
Bridging law and computer science, proposes counterfactual explanations (“what is the smallest change to your profile that would have resulted in loan approval?”) as a practical remedy that avoids disclosing proprietary model weights.
In English: original text written in English
In Polish: no Polish edition
-
critical perspective 2019 · English
Cynthia Rudin, Stop Explaining Black Box Machine Learning Models for High Stakes Decisions and Use Interpretable Models Instead
The sharpest methodological critique of post-hoc XAI (“Nature Machine Intelligence” 1, pp. 206–215): argues that in high-stakes tabular domains (criminal justice, credit, medicine), post-hoc approximations are inherently unfaithful and unnecessary because intrinsically interpretable models achieve comparable accuracy.
In English: original text written in English
In Polish: no Polish edition
-
critical perspective 2016 · English
Zachary C. Lipton, The Mythos of Model Interpretability
A classic essay dissecting how “interpretability” is used as a catch-all label for distinct, often conflicting desiderata (simulatability, decomposability, algorithmic transparency, post-hoc rationalization), while challenging the myth that linear models are always human-intelligible.
In English: original text written in English
In Polish: no Polish edition
-
cross-disciplinary 2019 · English
Tim Miller, Explanation in Artificial Intelligence: Insights from the Social Sciences
A comprehensive survey of philosophy, cognitive psychology, and sociology of explanation (“Artificial Intelligence” 267): shows that humans seek contrastive (“why P rather than Q?”), selective, and conversational explanations rather than exhaustive lists of mathematical feature weights.
In English: original text written in English
In Polish: no Polish edition
-
introduction & synthesis 2021 · English
Przemysław Biecek, Tomasz Burzykowski, Explanatory Model Analysis: Explore, Explain, and Examine Predictive Models
A systematic textbook of model-agnostic explanation methods (Chapman & Hall/CRC) coauthored by Warsaw University of Technology statistician Przemysław Biecek, creator of the widely used DALEX ecosystem.
In English: original text written in English
In Polish: Polish edition not verified
Primary-Source Quotes
These counterfactual explanations describe the smallest change to the world that can be made to obtain a desirable outcome, or to arrive at the closest possible world, without needing to explain the internal logic of the system.