AI Architecture #117
In-context learning
original term: in-context learning (Eng.) · uczenie w kontekście, uczenie z kontekstu, few-shot prompting
Global-circulation concept — no documented lineage in Central Europe. jump to documentation ↓
Working Definition
In-context learning (ICL) is the ability of a pretrained sequence model—most notably a Transformer language model—to adapt to and perform a novel task at inference time solely by conditioning on instructions or input–output demonstrations placed inside its active context window, without any gradient updates or changes to its weights. The model is not fine-tuned; whatever “learning” occurs happens entirely inside the temporary activation states of a single forward pass and vanishes the moment the context window is cleared. In its precise technical sense, the term designates an emergent computational mechanism whose internal implementation (Bayesian concept selection, induction-head circuits, or implicit gradient descent) is a central object of theoretical machine-learning research. In everyday practitioner talk, it is frequently conflated with few-shot prompting—that is, the user’s act of pasting examples into a prompt, rather than the surprising fact that a frozen network can execute an inner learning loop without updating parameters.
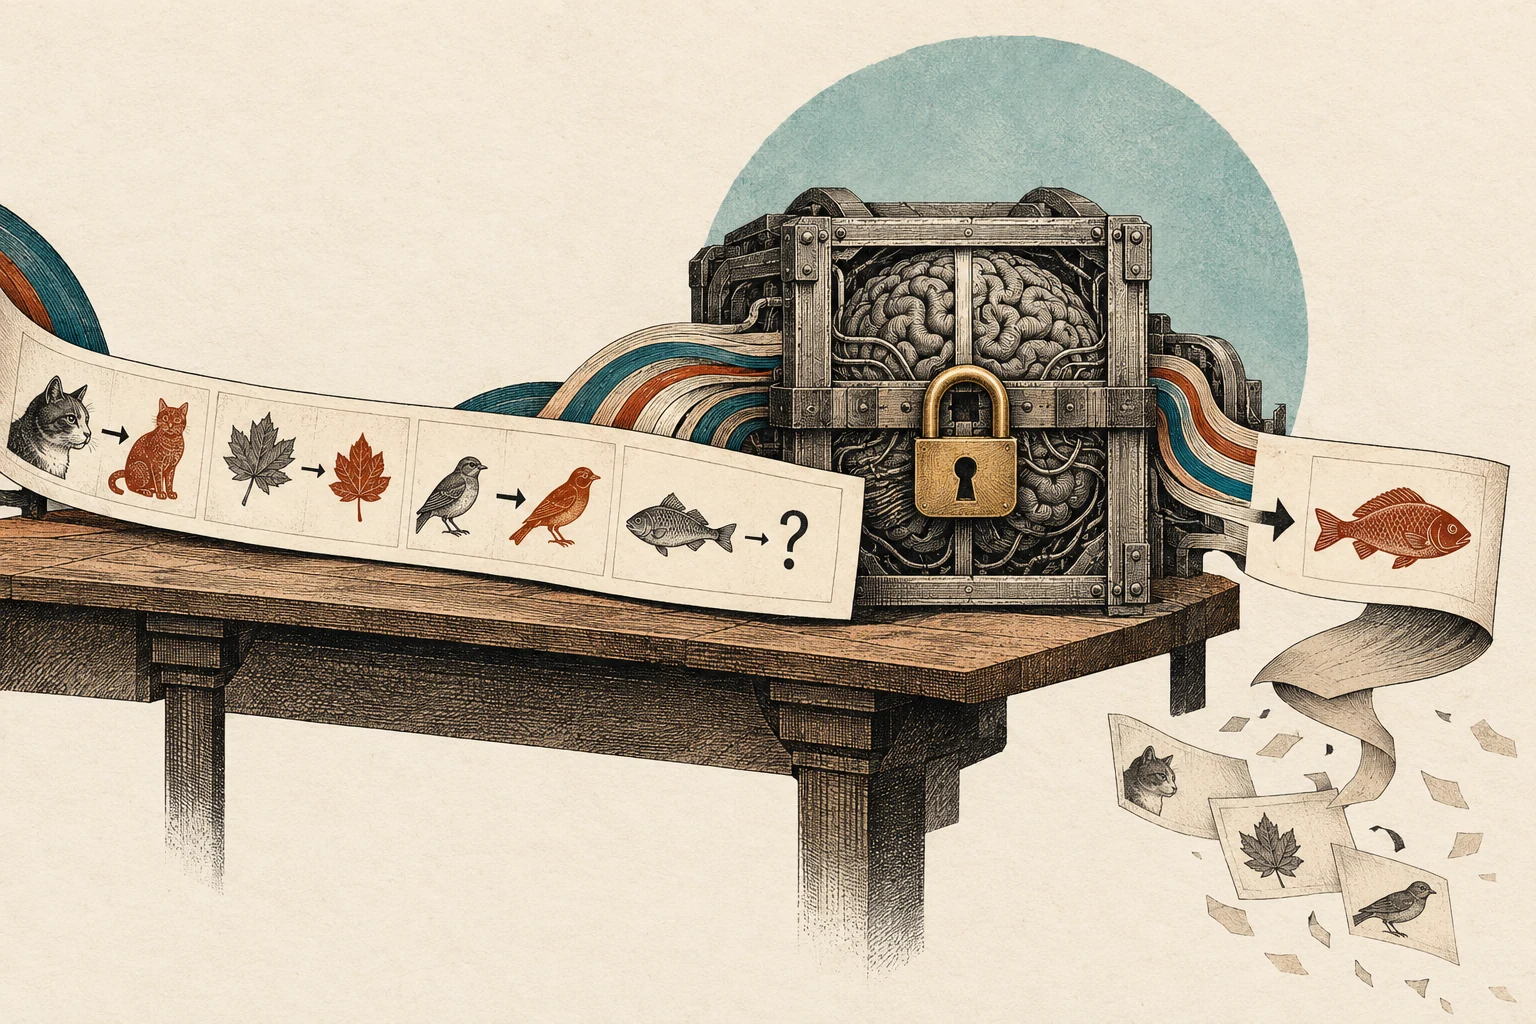
Examples in the active prompt guide the output without changing model weights, and the pattern disappears once it leaves the context window.
AI-assisted illustration · conceptual metaphor View in visual quiz →Genesis and Global Lineage
The term was coined by Tom B. Brown and his OpenAI co-authors in the May 2020 GPT-3 paper Language Models are Few-Shot Learners, deliberately replacing earlier, ambiguous phrases like “zero-shot transfer” that confused the absence of gradient updates with the absence of task examples. In Footnote 1 and Figure 1.1 of that paper, the authors framed unsupervised pretraining across the internet as the “outer loop” of meta-learning, and defined in-context learning as the “inner loop” occurring within the activations of each forward sequence. The broader idea that a neural network with fixed weights could learn new tasks dynamically from its inputs had deep roots in earlier meta-learning research—most notably Jürgen Schmidhuber’s “Fast Weight Programmers” (1992) and Sepp Hochreiter, A. Steven Younger, and Peter R. Conwell’s work on meta-learning with recurrent LSTMs (2001)—and had been prefigured in OpenAI’s GPT-2 paper (Radford et al., 2019), which showed that natural-language prompts could specify tasks zero-shot. What made May 2020 a watershed was the empirical discovery that the gap between zero-shot and few-shot in-context performance widened dramatically as model scale increased from 125 million to 175 billion parameters. From 2021 onward, in-context learning evolved from an empirical observation into a major theoretical research program bridging statistical learning theory, mechanistic interpretability, and optimization.
Central European Lineage
We found no documented link between this concept and the intellectual history or historical experience of Central Europe.
We found no documented link between this concept and the intellectual history or historical experience of Central Europe (by our methodology, this means “none found,” not “none exists”; as of October 2026).
Why Now
Between 2020 and 2026, in-context learning became the invisible foundation of how almost every consumer and enterprise interacts with artificial intelligence. Before 2020, deploying a language model like BERT for a new corporate classification or extraction task required collecting thousands of labeled examples, running GPU fine-tuning via backpropagation, and hosting a separate copy of the modified weights for every single task; thanks to in-context learning, a single frozen foundation model can serve ten thousand completely different downstream workflows simultaneously simply by swapping the text in the prompt prefix. Furthermore, between 2023 and 2026, the expansion of context windows from 2,048 tokens (in GPT-3) to 128,000, 1 million, and 2 million tokens (in Gemini 1.5/2.0 and Claude 3) transformed the scale of the phenomenon from “few-shot learning” (3 to 10 examples) to many-shot in-context learning, where users feed hundreds of examples, an entire codebase, or a whole textbook grammar of an endangered language into a single prompt. Simultaneously, landmark mechanistic studies between 2022 and 2024—identifying “induction heads” inside Transformer circuits (Olsson et al., 2022) and proving that linear attention layers can literally implement steps of gradient descent in their forward activations (von Oswald et al., 2023; Akyürek et al., 2023)—made in-context learning the premier Exhibit A in the scientific debate over whether large models merely memorize training data or synthesize genuine learning algorithms inside their weights.
Explanatory Power
The concept separates two capacities that popular commentary on AI persistently confuses: what a model stores in its permanent parameters versus what it can compute dynamically from its active working memory. First, it explains how a completely frozen network can adapt instantly to user-specific rules, private schemas, or newly invented notation that did not exist when pretraining ended—without suffering the “catastrophic forgetting” that plagues traditional gradient fine-tuning. Second, it illuminates the surprising findings of Sewon Min and colleagues (Rethinking the Role of Demonstrations, 2022), who showed that on many standard NLP benchmarks, randomly scrambling the ground-truth output labels in few-shot examples barely reduced accuracy: in those regimes, in-context demonstrations work primarily by telling the model the expected input distribution, the label space, and the output format, activating a task the model already knows from pretraining. Third, it unifies seemingly disparate engineering patterns—few-shot prompting, Retrieval-Augmented Generation (RAG), system prompts, and agentic scratchpads—as variations of a single phenomenon in which context-window activations function as temporary, per-request “fast weights.”
Axes of Debate
Task location (Bayesian retrieval) versus genuine on-the-fly algorithm execution (in-context gradient descent)
Proponents of the task-location view—such as Laria Reynolds and Kyle McDonell (2021), Sewon Min et al. (2022), and Sang Michael Xie et al. (2022), who model ICL as implicit Bayesian inference—argue that in-context examples primarily supply statistical cues that allow the model to infer which latent concept or skill, already acquired during pretraining, should be activated. Conversely, optimization theorists led by Ekin Akyürek et al. (2023), Johannes von Oswald et al. (2023), and Garg et al. (2022) prove on synthetic functions and linear regression tasks that Transformers trained from scratch learn to execute explicit steps of ordinary least squares or gradient descent inside their forward pass to fit wholly novel input–output mappings that could not have been memorized. Strongest counterargument: Recent reconciliation studies (such as Pan et al., 2023, separating “task recognition” from “task learning,” and work on many-shot ICL in 2024) show that both mechanisms coexist inside large models: with 3 to 5 examples on familiar natural-language tasks, Bayesian task recognition dominates (which is why random labels still work), whereas as model scale and the number of in-context examples grow into the dozens or hundreds, genuine algorithmic task learning takes over and overrides pretraining priors. Nature of the dispute: substantive — an exemplary scientific debate resolved through precise synthetic experiments and mechanistic circuit probing rather than rhetoric.
Abrupt phase-change emergence (induction heads) versus smooth metric continuum
Mechanistic interpretability researchers at Anthropic (Catherine Olsson, Nelson Elhage, Neel Nanda et al., 2022) demonstrated that during the pretraining of a Transformer, in-context learning ability surges during a sudden, distinct “phase change” in the loss curve that coincides with the spontaneous formation of two-layer attention circuits called induction heads (where one head tracks the previous token and a second head searches for prior occurrences of the current token to copy what followed it). Strongest counterargument: Critics of abrupt emergence (such as Schaeffer, Miranda, and Koyejo, 2023) argue that while induction-head formation is a real training dynamic, downstream few-shot benchmark curves often look sharper than they are because of non-linear evaluation metrics, and simple n-gram copying accounts for only the most basic layer of in-context reasoning. Nature of the dispute: substantive — it concerns how microscopic circuit formation during training maps onto macroscopic capability scaling curves.
Million-token in-context learning versus parameter fine-tuning
With the arrival of million-token context windows and KV-cache prefix caching in 2024–2025, many applied AI engineers argue that in-context learning (paired with RAG) has rendered domain-specific weight fine-tuning largely obsolete for enterprise knowledge tasks: why run expensive gradient updates that risk breaking model alignment when you can simply place hundreds of examples or a whole manual directly into the cached context? Strongest counterargument: Systems engineers and fine-tuning advocates reply that processing tens of thousands of context tokens on every query incurs permanent inference latency, memory bandwidth costs, and “lost in the middle” attention degradation (Liu et al., 2023), whereas parameter-efficient fine-tuning (LoRA) bakes domain behavior permanently into compact weights at zero ongoing token cost. Nature of the dispute: substantive — a shifting engineering trade-off governed by GPU memory pricing, prefix-caching economics, and how often the underlying task rules change.
Underappreciated Angle
In-context learning is almost universally celebrated as a capability breakthrough, yet it is simultaneously the architectural root of the hardest security and evaluation problems in modern AI. Because ICL allows tokens inside the context window to act as temporary “fast weights” that reprogram the model’s forward pass on the fly, every piece of text entering the context window can alter what program the model executes. When a developer puts examples in a prompt, we call it in-context learning; when an external webpage, email, or PDF read by an AI agent contains hidden instructions or adversarial examples that hijack behavior, we call it indirect prompt injection or many-shot jailbreaking (shown by Anthropic in 2024, where pasting hundreds of fictional dialogues of a compliant assistant into a long context window systematically overrode RLHF safety training). In-context learning and prompt injection are the exact same forward-pass reprogramming mechanism used by different actors. Consequently, if a model’s effective runtime weights are co-determined by its current context, there is no such thing as auditing “the model” in isolation—every safety guarantee and capability score is conditional on the context distribution encountered in the wild.
One-Sentence Takeaway
A language model does not “learn” from your prompt examples by remembering them for tomorrow; it learns in the sense that for the duration of a single forward pass, your context tokens act as temporary weights—meaning that anyone who controls the context window momentarily reprograms the machine.
Related Concepts Network
How this concept reinforces, constrains, or complements other analytical frameworks in the corpus. View on graph →
-
Large language models (LLMs) reinforces
In-context learning is the defining capability that separated large language models from earlier task-specific NLP networks and justified treating LLMs as a general-purpose class of systems.
-
Prompt engineering complements
Prompt engineering is the human-side practice of formatting instructions and demonstrations to steer the internal mechanism that in-context learning describes on the model side.
-
Transformer reinforces
Multi-head self-attention provides the physical routing substrate that allows a model to compare prompt demonstrations with the current query token; without attention circuits, in-context learning has no carrier.
-
Scaling laws reinforces
The efficiency of in-context learning scales steeply with model size, which Brown et al. (2020) plotted as a distinct family of scaling curves separating few-shot from zero-shot performance.
-
Emergence in tension
The debate over whether in-context learning appears abruptly above a critical parameter threshold or grows smoothly along continuous metrics sits at the heart of the controversy over emergent abilities.
-
RAG (Retrieval-Augmented Generation) complements
Retrieval-augmented generation injects retrieved reference documents rather than task demonstrations into the context window, relying on the exact same forward-pass conditioning capacity.
-
Model hallucinations constrains
Demonstrations in the prompt can constrain output format and style, but cannot supply factual knowledge absent from both the pretraining weights and the provided context.
Reading Canon & Translation Bridge
Foundational texts, introductions, and critical perspectives—with availability of English and Polish editions.
-
foundational text 2020 · English
Tom B. Brown i in., Language Models are Few-Shot Learners
The landmark GPT-3 paper that coined the term and defined it as the inner loop of meta-learning occurring entirely within the forward pass of a sequence without gradient updates (Section 1 and Figure 1.1).
In English: original text written in English
In Polish: no Polish edition
-
foundational text 2022 · English
Sang Michael Xie, Aditi Raghunathan, Percy Liang, Tengyu Ma, An Explanation of In-context Learning as Implicit Bayesian Inference
The first influential theoretical account (ICLR 2022): models in-context learning as implicit Bayesian inference in which prompt examples provide evidence that narrows down a latent document-level concept learned during pretraining.
In English: original text written in English
In Polish: no Polish edition
-
critical perspective 2022 · English
Sewon Min i in., Rethinking the Role of Demonstrations: What Makes In-Context Learning Work?
Provocative empirical experiments (EMNLP 2022) showing that replacing ground-truth labels in few-shot demonstrations with random labels barely degrades classification accuracy—challenging the naive view that the model learns input–label mappings from scratch at test time.
In English: original text written in English
In Polish: no Polish edition
-
critical perspective 2023 · English
Ekin Akyürek, Dale Schuurmans, Jacob Andreas, Tengyu Ma, Denny Zhou, What learning algorithm is in-context learning? Investigations with linear models
An ICLR 2023 study using synthetic linear regression tasks to prove that Transformer layers can implement exact steps of ridge regression and gradient descent inside their forward-pass activations.
In English: original text written in English
In Polish: no Polish edition
-
cross-disciplinary 2023 · English
Johannes von Oswald i in., Transformers learn in-context by gradient descent
An ICML 2023 constructive proof showing how a single linear self-attention layer mathematically executes a step of gradient descent on the in-context demonstrations, bridging forward-pass attention and classical optimization.
In English: original text written in English
In Polish: no Polish edition
-
cross-disciplinary 2022 · English
Catherine Olsson, Nelson Elhage, Neel Nanda i in., In-context Learning and Induction Heads
A foundational mechanistic-interpretability study from Anthropic linking the sudden emergence of in-context learning during training to a phase change in which two-layer “induction heads” form to copy and complete abstract patterns.
In English: original text written in English
In Polish: no Polish edition
-
introduction & synthesis 2022 · English
Qingxiu Dong i in., A Survey on In-context Learning
A comprehensive survey organizing definitions, pretraining warmup strategies, demonstration selection and ordering methods, and theoretical explanations of how ICL works.
In English: original text written in English
In Polish: no Polish edition
Primary-Source Quotes
To avoid this confusion, we use the term “meta-learning” to capture the inner-loop / outer-loop structure of the general method, and the term “in context-learning” to refer to the inner loop of meta-learning.