AI Architecture #116
Prompt engineering
original term: prompt engineering (Eng.) · projektowanie poleceń, inżynieria promptów, prompt programming
Global-circulation concept — no documented lineage in Central Europe. jump to documentation ↓
Working Definition
Prompt engineering is the systematic practice of designing, structuring, and optimizing the input text (and multimodal context) fed to a generative model so as to elicit desired behaviors—such as a specific output schema, persona, reasoning trajectory, or epistemic constraint—without modifying the model’s underlying weights. In its rigorous technical sense, it involves constructing parameterized templates, curating few-shot demonstrations, orchestrating intermediate reasoning steps, and evaluating prompt variants quantitatively across held-out test suites. In popular and commercial usage since 2022, the phrase simply means “knowing how to talk to ChatGPT” and has been marketed as a standalone white-collar career or a collection of copy-paste “magic phrases.” Keeping the two apart is essential: engineering a prompt pipeline is an empirical discipline measured by variance and error rates across distributions of inputs, whereas folk prompting relies on single-shot anecdotes that frequently collapse when the model checkpoint updates.
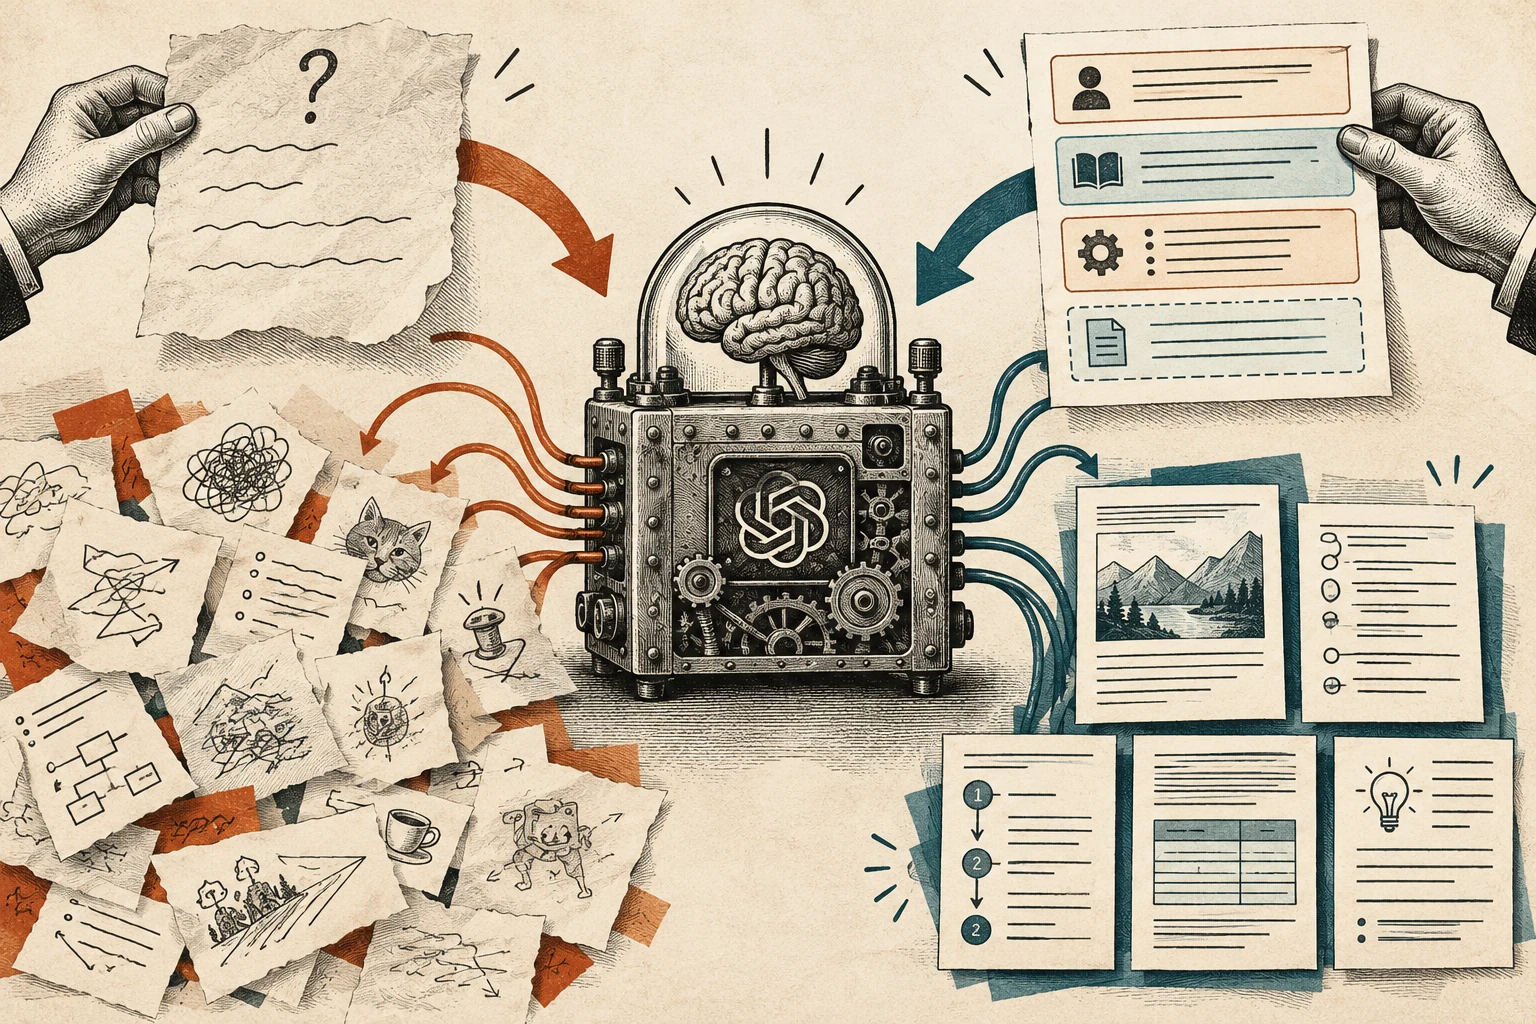
Clarifying the task, context, and output format helps elicit a more useful response from the same model, though good prompting does not replace verification.
AI-assisted illustration · conceptual metaphor View in visual quiz →Genesis and Global Lineage
The practice preceded the name. When OpenAI published the GPT-3 paper (Language Models are Few-Shot Learners, Brown et al., May 2020) and opened its commercial API that summer, early users and researchers discovered that rewording a natural-language task description or re-ordering a handful of input–output examples could swing benchmark accuracy by thirty or forty percentage points without touching a single gradient. In February 2021, Laria Reynolds and Kyle McDonell published Prompt Programming for Large Language Models: Beyond the Few-Shot Paradigm, coining “prompt programming” and arguing that prompts do not teach a model new concepts on the fly, but rather use natural-language cues to locate and activate task spaces the model has already absorbed during pretraining. In July 2021, Pengfei Liu and colleagues systematized the emerging field in their landmark survey Pre-train, Prompt, and Predict, demonstrating how diverse NLP tasks could be reformulated as cloze or prefix fill-in-the-blank templates. In January 2022, Jason Wei and colleagues at Google introduced Chain-of-Thought (CoT) Prompting, proving that prompting a large model to emit step-by-step intermediate reasoning before stating an answer unlocked dramatic gains on arithmetic and symbolic tasks, followed in May 2022 by Takeshi Kojima et al.’s discovery that simply appending “Let’s think step by step” (zero-shot CoT) triggered the same behavior. After ChatGPT’s release in November 2022, software-engineering researchers led by Jules White (February 2023) codified reusable “prompt patterns” modeled on object-oriented design patterns, while in 2023–2026 frameworks like DSPy (Khattab et al.) and automated prompt optimizers began replacing hand-tuned strings with programmatic compilation.
Central European Lineage
We found no documented link between this concept and the intellectual history or historical experience of Central Europe.
We found no documented link between this concept and the intellectual history or historical experience of Central Europe (by our methodology, this means “none found,” not “none exists”; as of October 2026).
Why Now
Three milestones explain why prompt engineering became a focal point of both software practice and labor-market hype between 2020 and 2026. First, the launch of the GPT-3 API (June 2020) and ChatGPT (November 2022) turned natural language into the universal runtime interface for hundreds of millions of users, briefly sparking a 2023 gold rush of six-figure job postings for “prompt engineers” and an entire cottage industry of online courses selling secret templates. Second, in June 2024, Sander Schulhoff and dozens of collaborators published The Prompt Report, a massive taxonomy cataloging 58 distinct text-prompting techniques and 40 multimodal variants—bringing order to a sprawling empirical literature while acknowledging pervasive terminological confusion. Third, between 2024 and 2026, two forces reshaped the field simultaneously: on one side, instruction-tuned models and inference-time “reasoning” models (such as OpenAI’s o1/o3 series and DeepSeek-R1) internalized chain-of-thought search into their own post-training, rendering many manual prompting tricks redundant and shifting practitioner focus toward programmatic context engineering (deciding what data, tools, and memory state enter the context window); on the other side, the rise of autonomous LLM agents made prompt injection—where untrusted external text hijacks the model’s instructions—the number-one application security vulnerability in enterprise AI.
Explanatory Power
The concept makes visible a foundational truth of modern AI evaluation: a model’s observed behavior is never a property of the model weights alone, but a joint function of the model-plus-prompt pair. Without this lens, benchmark leaderboards and capability claims are nearly impossible to interpret. First, as Yao Lu and colleagues demonstrated in Fantastically Ordered Prompts (2021), simply changing the permutation order of four identical few-shot examples in a prompt can drive a model’s classification accuracy from state-of-the-art (nearly 90%) down to random guessing (50%)—proving that half of what looked like “model capability” was actually prompt-order luck. Second, Chain-of-Thought prompting (Wei et al., 2022) revealed a crucial distinction between latent competence and elicited performance: a model that fails flatly when forced to output a direct numerical answer in a single token pass often succeeds when prompted to write out intermediate scratchpad steps in its context window, because the generated tokens act as external working memory for subsequent attention layers. Third, the lens explains why two companies deploying the exact same frontier API endpoint experience wildly different reliability: the difference rarely lies in the model weights, but in how their system prompts, JSON schema constraints, and retrieved context chunks structure the probability distribution before the first output token is sampled.
Axes of Debate
A durable engineering discipline versus a transient historical prosthesis
Software-engineering researchers and enterprise practitioners (such as Jules White et al., 2023, and the authors of The Prompt Report, 2024) treat prompt engineering as a permanent new layer of the software stack—requiring standardized pattern catalogs, version control, and regression testing to translate human institutional rules into model context. Strongest counterargument: Researchers in automated optimization (such as Yongchao Zhou et al., Large Language Models Are Human-Level Prompt Engineers, 2022, and Omar Khattab’s DSPy team) demonstrate that algorithms and LLMs themselves systematically outperform human wordsmiths at discovering optimal prompt strings, while each new generation of RLHF and reasoning models renders last year’s folklore (“take a deep breath,” “I will tip you $200”) obsolete—suggesting that manual prompt tweaking was a temporary workaround for early unaligned models. Nature of the dispute: substantive — it is being adjudicated empirically as manual “string whispering” withers away while structural context engineering and programmatic prompt compilation endure.
Natural-language programming versus statistical distribution steering
Following Reynolds and McDonell (2021) and Andrej Karpathy’s famous quip that “the hottest new programming language is English,” many developers frame prompts as declarative programs written in natural language whose semantics can be modularized like code. Strongest counterargument: Computational linguists (building on Bender and Koller, 2020) and formal-methods researchers point out that calling prompting “programming” is a dangerous category error: a true programming language offers deterministic syntax and formal execution guarantees, whereas a prompt merely conditions a high-dimensional probability distribution over tokens—where adding a polite adjective or an extra newline can unpredictably flip a downstream logical decision. Nature of the dispute: mixed — partly a metaphorical dispute over vocabulary, but with direct substantive consequences for whether engineers treat LLM outputs as trusted code execution or as untrusted stochastic samples.
Task performance optimization versus security boundary enforcement
The vast majority of prompting literature optimizes for task accuracy and helpfulness, treating the prompt as a cooperative workspace. Security researchers (such as Simon Willison, who coined “prompt injection” in 2022, and Florian Tramèr’s group) warn that because an LLM processes system instructions and untrusted user or web data inside a single undifferentiated sequence of tokens, no amount of clever defensive wording in a system prompt (“ignore all malicious instructions below”) can guarantee security against adversarial overrides. Strongest counterargument: Application builders reply that while prompt-level defenses cannot provide cryptographic-grade isolation, layered system-prompt guardrails, input/output classifiers, and privilege separation outside the LLM remain indispensable pragmatic mitigations until architectural separation of instruction and data channels is solved. Nature of the dispute: substantive — it concerns which layer of a socio-technical system can bear the burden of security guarantees when the underlying neural network lacks a von Neumann separation between code and data.
Underappreciated Angle
The least examined aspect of prompt engineering is the fragile epistemic status of its own body of knowledge—which for its first several years resembled pre-scientific humoral medicine more than computer science. Thousands of viral posts and even peer-reviewed papers reported that telling a model “you are a world-class expert,” offering it a fictional monetary tip, or threatening it with punishment boosted benchmark scores—without testing whether those gains survived across different model families, different random seeds, or minor rephrasings of the evaluation dataset. When systematic replication studies finally tested these claims across diverse benchmarks, most persona prompts and emotional appeals showed erratic, near-zero average effect sizes, often helping on one subset of questions while hurting on another. Furthermore, as Lu et al. (2021) proved, a prompt configuration that is optimal for one checkpoint frequently degrades performance when transferred to a larger model or a rival lab’s API. The real intellectual breakthrough of prompt engineering is therefore the exact opposite of collecting “magic spells”: it is the realization that every prompt is an empirical hypothesis about a black-box distribution that must be versioned, ablated against a multi-hundred-example validation set, and automatically re-compiled whenever the underlying model changes. Those who run evaluation harnesses practice engineering; those who hoard prompt templates practice digital alchemy.
One-Sentence Takeaway
A prompt is not a question addressed to a mind, but a runtime boundary condition imposed on a probability distribution—and anyone who grasps that stops asking “what can the model do?” and starts testing “what does this specific model-plus-context pair reliably produce?”
Related Concepts Network
How this concept reinforces, constrains, or complements other analytical frameworks in the corpus. View on graph →
-
In-context learning reinforces
Prompt engineering is the practical, human-facing craft of steering the internal mechanism that in-context learning describes on the model side—adapting behavior via context tokens without weight updates.
-
Large language models (LLMs) complements
Because the text prompt is the primary runtime interface through which users and applications steer a large language model, the discipline of prompt design co-evolves with model scale.
-
RLHF in tension
Instruction tuning and RLHF internalize much of the scaffolding that early prompt engineers had to supply manually, while simultaneously changing the behavioral priors to which prompts must be tuned.
-
Prompt injection constrains
The exact same natural-language channel through which a developer steers the model is open to untrusted external data; a prompt has no hardware-enforced boundary between code and data.
-
Model hallucinations complements
Prompting techniques such as chain-of-thought and explicit grounding instructions lower the frequency of fabrications, but cannot eliminate them because they do not alter the underlying probabilistic sampling mechanism.
-
RAG (Retrieval-Augmented Generation) complements
Dynamically stuffing retrieved document chunks into the context window at query time is an automated, programmatic form of prompt engineering (“context engineering”).
-
Scaling laws constrains
As models scale in size and post-training reasoning, many brittle prompt incantations become obsolete, suggesting that much of early prompt engineering was a temporary prosthesis for model weakness.
Reading Canon & Translation Bridge
Foundational texts, introductions, and critical perspectives—with availability of English and Polish editions.
-
foundational text 2020 · English
Tom B. Brown i in., Language Models are Few-Shot Learners
The GPT-3 paper demonstrating that natural-language task descriptions paired with a handful of input–output demonstrations in the context window suffice to steer a frozen model across dozens of tasks.
In English: original text written in English
In Polish: no Polish edition
-
foundational text 2021 · English
Laria Reynolds, Kyle McDonell, Prompt Programming for Large Language Models: Beyond the Few-Shot Paradigm
The first paper to theorize prompting as programming in natural language, arguing that few-shot examples function less by teaching a new skill than by locating an existing capability in latent space, and introducing the concept of a “metaprompt.”
In English: original text written in English
In Polish: no Polish edition
-
introduction & synthesis 2021 · English
Pengfei Liu i in., Pre-train, Prompt, and Predict: A Systematic Survey of Prompting Methods in Natural Language Processing
The comprehensive survey that named the “pre-train, prompt, and predict” paradigm in NLP and established a unified mathematical notation for cloze and prefix prompts.
In English: original text written in English
In Polish: no Polish edition
-
foundational text 2022 · English
Jason Wei i in., Chain-of-Thought Prompting Elicits Reasoning in Large Language Models
The single most influential prompting discovery: providing exemplars with explicit intermediate reasoning steps dramatically boosts arithmetic, commonsense, and symbolic performance in sufficiently large models.
In English: original text written in English
In Polish: no Polish edition
-
introduction & synthesis 2023 · English
Jules White i in., A Prompt Pattern Catalog to Enhance Prompt Engineering with ChatGPT
A software-engineering formalization of prompting: organizes recurring prompt structures into a catalog of reusable patterns modeled on the classic Gang of Four object-oriented design patterns.
In English: original text written in English
In Polish: no Polish edition
-
critical perspective 2022 · English
Yongchao Zhou i in., Large Language Models Are Human-Level Prompt Engineers
Introduces Automatic Prompt Engineer (APE), demonstrating that LLMs can generate and select task instructions that match or beat human-written prompts on 19 of 24 benchmarks—challenging the durability of prompt engineering as a manual human profession.
In English: original text written in English
In Polish: no Polish edition
-
critical perspective 2021 · English
Yao Lu i in., Fantastically Ordered Prompts and Where to Find Them: Overcoming Few-Shot Prompt Order Sensitivity
Exposes the extreme brittleness of prompting: merely permuting the order of the exact same few-shot examples swings classification accuracy between state-of-the-art and near-random chance, and optimal orderings do not transfer across models.
In English: original text written in English
In Polish: no Polish edition
-
cross-disciplinary 2020 · English
Emily M. Bender, Alexander Koller, Climbing towards NLU: On Meaning, Form, and Understanding in the Age of Data
A philosophy-of-language critique showing that models trained purely on surface form lack access to communicative intent—explaining why prompting a statistical model differs fundamentally from giving instructions to a human colleague.
In English: original text written in English
In Polish: no Polish edition