AI Architecture #133
Algorithmic bias
original term: algorithmic bias (Eng.) · uprzedzenia algorytmiczne, bias in computer systems, dyskryminacja algorytmiczna
Central European lineage: 1 thread (historical experience) · 2015–2019 · jump to documentation ↓
Working Definition
Algorithmic bias is the systematic, repeatable, and unfair differentiation of a computational system’s outputs to the disadvantage of certain individuals or social groups, regardless of the subjective intentions of its designers. Operationally, it refers not to random noise or isolated glitches, but to directional error or allocation disparity that correlates with a protected characteristic (such as race, gender, age, disability, or socioeconomic status) or with its statistical proxies. Whereas everyday talk reduces the phenomenon to “a racist algorithm” or “bad training data,” technical and legal analysis distinguishes three distinct layers where bias enters: preexisting social and institutional inequalities encoded in historical data and target labels, technical design choices (feature selection, loss functions, proxy metrics, and threshold cutoffs), and emergent mismatches when a model is deployed in a social context different from the one in which it was calibrated. Diagnosing algorithmic bias requires specifying which of these layers failed, because each demands a completely different remedy.
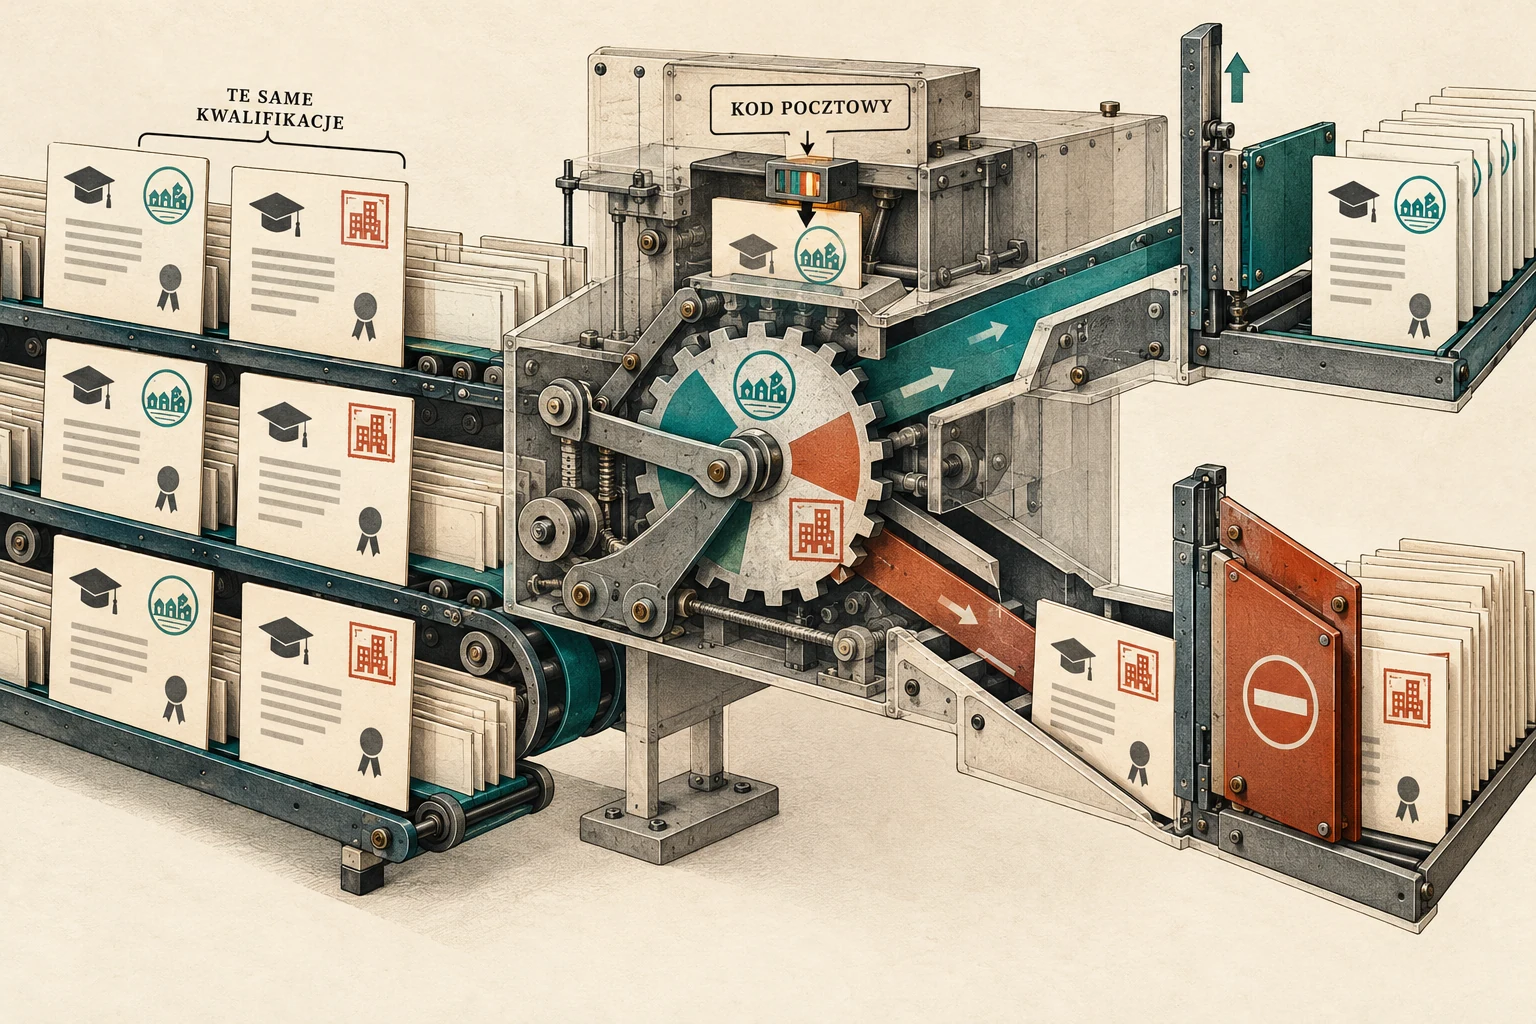
The system repeatedly sorts equally qualified people by address, which acts as a proxy for group characteristics. The drawing shows one possible mechanism of unfairness rather than all sources of algorithmic bias.
AI-assisted illustration · conceptual metaphor View in visual quiz →Genesis and Global Lineage
The concept has lived two historical lives. Its quieter academic life began in 1996, when Batya Friedman and Helen Nissenbaum published Bias in Computer Systems (ACM Transactions on Information Systems), defining bias as systematic and unfair discrimination and dividing it into preexisting, technical, and emergent forms—illustrated through airline reservation systems and automated medical school admissions. Its explosive public life began between 2014 and 2018 as machine learning moved into high-stakes social allocation. In 2016, Solon Barocas and Andrew D. Selbst (Big Data’s Disparate Impact) showed how standard data-mining pipelines reproduce structural discrimination without human prejudice; in May 2016, ProPublica’s Machine Bias audited the COMPAS recidivism risk tool in Florida, sparking the mathematical discovery that competing fairness definitions cannot be satisfied simultaneously; Cathy O’Neil (Weapons of Math Destruction, 2016) and Safiya Umoja Noble (Algorithms of Oppression, 2018) brought the critique into public consciousness; and Joy Buolamwini and Timnit Gebru’s Gender Shades (2018) proved that commercial facial-analysis APIs misclassified darker-skinned women at rates up to 34.7% versus 0.8% for lighter-skinned men. This wave built the interdisciplinary ACM FAccT community while also spawning a media shorthand that flattens socio-technical feedback loops into tales about biased engineers.
Central European Lineage
Poland provided one of Europe’s earliest documented case studies of algorithmic bias in public-sector welfare administration—years before the Dutch childcare benefits scandal (toeslagenaffaire) or the EU AI Act. Starting in May 2014, local public employment offices (urzędy pracy) across Poland were legally required to sort every registered unemployed person into one of three assistance profiles using a centralized software algorithm scoring 24 demographic and behavioral variables alongside a computer-assisted interview. Registrants assigned to Profile III—roughly 30% of the unemployed, disproportionately long-term unemployed people, single mothers, carers, and rural residents—were classified as “distant from the labor market” and automatically excluded from active training and subsidies. Because the Ministry of Labor treated the scoring weights as a trade secret, the Warsaw-based digital-rights NGO Panoptykon Foundation (Fundacja Panoptykon) used freedom-of-information litigation to extract the lookup tables, publishing a landmark English-language study in October 2015 (Profiling the Unemployed in Poland, by Jędrzej Niklas, Karolina Sztandar-Sztanderska, and Katarzyna Szymielewicz). Following a constitutional challenge by the Polish Ombudsman (Rzecznik Praw Obywatelskich), on June 6, 2018 the Constitutional Tribunal (Trybunał Konstytucyjny, case K 53/16) struck down the profiling regulation under constitutional data-protection guarantees, and the government abolished it by December 2019. Featured in AlgorithmWatch’s Automating Society (2019), the Polish case became a European precedent showing how an unvalidated scoring formula institutionalizes exclusion under a veneer of objectivity.
Documented regional lineage · Link: 1. Compiled: October 2026.
-
historical experience 4 years
Central European Source: Algorytmiczne profilowanie pomocy dla bezrobotnych; raport Fundacji Panoptykon „Profiling the Unemployed in Poland” (2015); wyrok Trybunału Konstytucyjnego K 53/16 (2018) — Profilowanie bezrobotnych w polskich urzędach pracy (2014–2019); Warsaw, Poland, 2015
Global Circulation: algorithmic bias and opacity in public-sector automated decision-making (AlgorithmWatch, “Automating Society”) — AlgorithmWatch / Jędrzej Niklas, 2019
historical experience
4 yearsAlgorytmiczne profilowanie pomocy dla bezrobotnych; raport Fundacji Panoptykon „Profiling the Unemployed in Poland” (2015); wyrok Trybunału Konstytucyjnego K 53/16 (2018) — Profilowanie bezrobotnych w polskich urzędach pracy (2014–2019)
2015 · Warsaw, Poland
algorithmic bias and opacity in public-sector automated decision-making (AlgorithmWatch, “Automating Society”)
2019 · AlgorithmWatch / Jędrzej Niklas
- Claim & Connection
- Between May 2014 and 2019, Polish public employment offices (urzędy pracy) algorithmically sorted registered jobseekers into three assistance profiles based on 24 variables and a scored computer interview; those assigned to Profile III (roughly 30% of registrants) were effectively cut off from active labor-market programs. The Warsaw-based digital rights NGO Panoptykon Foundation extracted the scoring rules through freedom-of-information litigation and published a landmark English-language case study in October 2015 exposing the system’s discriminatory and opaque design. On June 6, 2018, following a petition by the Polish Ombudsman (RPO), the Constitutional Tribunal (case K 53/16) ruled the profiling mechanism unconstitutional, and the government abolished it in 2019. The Polish case became one of Europe’s earliest documented benchmarks of public-sector algorithmic bias, featured prominently in AlgorithmWatch’s “Automating Society” report (2019).
- Source Documentation
-
- scholarly study Jędrzej Niklas, Karolina Sztandar-Sztanderska, Katarzyna Szymielewicz, „Profiling the Unemployed in Poland: Social and Political Implications of Algorithmic Decision Making”, Fundacja Panoptykon, Warszawa 2015; report page in the Panoptykon library (published October 14, 2015) with direct link to the full English PDF. panoptykon.org ↗
- reception / translation Jędrzej Niklas, „Poland: Government to scrap controversial unemployment scoring system”, AlgorithmWatch, 16 IV 2019; full article: three profiles, 24 variables, 2018 Constitutional Tribunal ruling, role of Panoptykon, abolition by December 2019. algorithmwatch.org ↗
- scholarly study „Szczegóły profilowania pomocy dla bezrobotnego mają być uregulowane w ustawie”, e-prawnik.pl, 30 VI 2018 (omówienie wyroku TK K 53/16); judgment date June 6, 2018, Article 34a(3c) ruled unconstitutional under Article 51(1) and (5) of the Polish Constitution. e-prawnik.pl ↗
- Historical Context
- All three sources confirm the full sequence: introduction in May 2014 across 24 scored dimensions, roughly 30% placed in Profile III with minimal support, FOI litigation by Panoptykon (2015 report), Constitutional Tribunal judgment K 53/16 of June 6, 2018 upon motion of the Ombudsman, and statutory abolition by December 2019.
Why Now
Three developments between 2018 and 2026 turned algorithmic bias into an enforceable legal and engineering category. First, public scandals forced institutional retreats: following Gender Shades (2018) and NIST evaluations (2019), IBM, Microsoft, and Amazon restricted police sales of facial recognition in 2020, while in January 2021 the Dutch cabinet resigned after an inquiry revealed that the tax authority’s risk-scoring algorithm had falsely flagged tens of thousands of low-income, dual-nationality families for childcare-benefit fraud (toeslagenaffaire). Second, hard statutory law arrived: the EU AI Act (2024) classifies systems used in hiring, creditworthiness, social benefits, education, and policing as “high-risk” (Annex III), mandating data governance to mitigate bias (Article 10) and permitting sensitive demographic data processing for bias audits; in the US, New York City’s Local Law 144 (2023) mandated annual bias audits for automated hiring tools. Third, generative foundation models after 2022 shifted the terrain from binary tabular classifiers to multimodal representation: in LLMs and image generators, bias manifests through stereotype amplification, dialectal performance gaps, cultural erasure of smaller languages, and whose worldview a model adopts as its “neutral” default.
Explanatory Power
The concept diagnoses discrimination without a discriminator, showing how a mathematically neutral optimization procedure produces exclusionary outcomes without human malice. First is redundant encoding and proxy variables: deleting the column labeled “race” or “gender” (“fairness through unawareness”) accomplishes nothing in high dimensions, because a model reconstructs protected attributes from correlated proxies like postal code, school district, or employment gaps. Second is label bias and proxy targets (Goodhart’s law in action): when Ziad Obermeyer et al. (2019) audited a commercial healthcare algorithm used on millions of U.S. patients, they found it assigned Black patients lower risk scores than equally sick white patients because it had been trained to predict future healthcare costs as a proxy for medical need, and unequal access meant less money had been spent on Black patients. Third is self-fulfilling feedback loops: a predictive policing model trained on past arrest records sends more patrols to previously over-policed neighborhoods, generating more arrests there, which then feed into the next retraining cycle as “confirmation” of the model’s accuracy.
Axes of Debate
Biased model versus faithful mirror of an unequal world
Many ML engineers and statisticians argue that when a model reflects real differences in historical base rates across groups (such as credit default rates or arrest records), the model is not “biased”—it is accurately estimating conditional probabilities in an unequal society, and blaming the thermometer for the fever confuses epistemology with politics. Critical scholars (Safiya Noble, Kate Crawford, Ruha Benjamin) and legal theorists (Sandra Wachter, Brent Mittelstadt, Chris Russell) reply that training an automated gatekeeper on historical inequality is an active institutional intervention locking past injustice into future allocation. Strongest counterargument: As Wachter, Mittelstadt, and Russell (2021) show, EU non-discrimination law is designed to transform unfair historical baselines rather than preserve them; a hiring or credit model projecting past structural exclusion into the future can violate equality law even if its statistical calibration is textbook-perfect. Nature of the dispute: substantive — concerning whether “unfairness” is measured against statistical fidelity to the status quo or legal commitments to equal opportunity.
Predictive calibration versus equal error rates (the impossibility theorems)
In the 2016 COMPAS controversy, Northpointe proved its risk score was well-calibrated across racial groups (a score of 7 meant the same re-arrest probability for Black and white defendants), while ProPublica proved it violated error-rate balance (among defendants who did not reoffend, Black defendants were nearly twice as likely to be falsely labeled high-risk). Strongest counterargument: Jon Kleinberg, Sendhil Mullainathan, and Manish Raghavan (2016) and Alexandra Chouldechova (2017) proved mathematically that whenever base rates differ between two groups, no imperfect classifier can satisfy predictive calibration, equal false-positive rates, and equal false-negative rates simultaneously. Choosing a fairness metric is an inescapable moral and political choice about which error hurts whom more. Nature of the dispute: substantive at its mathematical core, turning rhetorical when vendors cite one metric to claim a product is “unbiased” while concealing trade-offs on the others.
Technical debiasing versus refusal to deploy
Industry teams focus on algorithmic mitigation—reweighting samples, adding fairness regularizers, or collecting diverse facial images to equalize subgroup accuracy. Abolitionist critics and civil-rights advocates (Ruha Benjamin, Luke Stark, Joy Buolamwini) counter that for carceral or predatory applications—live police facial surveillance or welfare-fraud hunting—making a classifier equally accurate on darker skin merely makes an apparatus of surveillance or deprivation more efficient. Strongest counterargument: Where high-stakes allocation decisions must be made daily—medical triage, loan underwriting, resume screening—banning statistical models hands decisions back to unrecorded human discretion, whose prejudices are far harder to audit than model weights. Nature of the dispute: mixed — technical debates over debiasing algorithms intersect with a political disagreement over which institutional tasks should be automated at all.
Underappreciated Angle
Debates focus overwhelmingly on Friedman and Nissenbaum’s first two categories—biased data and mathematical metrics—while neglecting their third: emergent bias in human–computer interaction. Even a model that passes statistical fairness audits can become discriminatory inside a bureaucratic workflow: a score calibrated on urban patients is deployed in a rural clinic, or human caseworkers treat recommendations asymmetrically—rubber-stamping harsh denials for marginalized applicants because challenging the computer requires a lengthy memo, while overriding the algorithm for privileged applicants who know how to argue their case. Poland’s 2014–2019 unemployment profiling system illustrates this: overburdened clerks lacked the time and incentive to override Profile III labels, turning a “non-binding decision-support aid” into an iron cage. Algorithmic bias never resides solely inside neural weights; it crystallizes in the institutional power relation between the clerk, the screen, and the citizen who cannot talk back to the score.
One-Sentence Takeaway
A biased algorithm rarely lies about the empirical past; its danger is that it extracts a statistical truth from a history of unequal treatment and enforces that past as a rule upon the future.
Related Concepts Network
How this concept reinforces, constrains, or complements other analytical frameworks in the corpus. View on graph →
-
Explainable AI (XAI) complements
Without the ability to inspect which features or proxy variables drove a model’s prediction, algorithmic bias can only be detected statistically after the fact at the output layer.
-
Algorithmic management reinforces
When an algorithm allocates shifts, credit, or social welfare benefits, its systematic statistical errors cease to be a measurement problem and become an exercise of institutional power over human lives.
-
Goodhart’s law complements
Optimizing for a convenient proxy target (past arrests instead of actual offenses, healthcare spending instead of medical need) is one of the primary mechanisms through which structural bias enters a model.
-
Intersectionality reinforces
Buolamwini and Gebru’s “Gender Shades” audit proved that classification error rates compound at the intersection of gender and skin tone in ways invisible to single-axis evaluations.
-
Datafication reinforces
The more spheres of social life are converted into historical training data, the more deeply past institutional inequalities become encoded as the “ground truth” of predictive models.
-
AI governance complements
Mandatory bias audits, fundamental-rights impact assessments, and data-quality obligations in the EU AI Act represent the institutional response to a problem that is simultaneously technical and social.
-
Technological solutionism in tension
The promise that a biased social allocation can be “debiased” simply by adding a mathematical fairness constraint to the loss function reproduces the illusion that structural injustice has a purely engineering fix.
Reading Canon & Translation Bridge
Foundational texts, introductions, and critical perspectives—with availability of English and Polish editions.
-
foundational text 1996 · English
Batya Friedman, Helen Nissenbaum, Bias in Computer Systems
The foundational paper in “ACM Transactions on Information Systems” (vol. 14, no. 3) defining computer system bias as systematic and unfair discrimination and introducing the classic three-part taxonomy of preexisting, technical, and emergent bias.
In English: original text written in English
In Polish: no Polish edition
-
foundational text 2016 · English
Solon Barocas, Andrew D. Selbst, Big Data's Disparate Impact
A landmark article in the “California Law Review” (vol. 104, p. 671) showing step by step how data mining produces discriminatory disparate impact without any malicious intent—and why traditional anti-discrimination law struggles to address it.
In English: original text written in English
In Polish: no Polish edition
-
foundational text 2018 · English
Joy Buolamwini, Timnit Gebru, Gender Shades: Intersectional Accuracy Disparities in Commercial Gender Classification
An empirical audit of three commercial gender-classification systems (PMLR 81, pp. 77–91): error rates reached 34.7% for darker-skinned women compared to 0.8% for lighter-skinned men, establishing the gold standard for intersectional algorithmic auditing.
In English: original text written in English
In Polish: no Polish edition
-
cross-disciplinary 2016 · English
Julia Angwin, Jeff Larson, Surya Mattu, Lauren Kirchner, Machine Bias
The May 23, 2016 ProPublica investigation into the COMPAS recidivism risk algorithm, which ignited the foundational mathematical debate over whether algorithmic fairness should be measured by predictive calibration or by equal false-positive rates across groups.
In English: original text written in English
In Polish: no Polish edition
-
introduction & synthesis 2016 · English
Cathy O'Neil, Weapons of Math Destruction: How Big Data Increases Inequality and Threatens Democracy
The most accessible public introduction, written by a mathematician with Wall Street quant experience; vividly explains destructive feedback loops in which opaque models generate the very data that appears to validate their biases.
In English: original text written in English
In Polish: “Broń matematycznej zagłady. Jak algorytmy zwiększają nierówności i zagrażają demokracji”, Wydawnictwo Naukowe PWN 2017, trans. Marcin Z. Zieliński
-
cross-disciplinary 2018 · English
Safiya Umoja Noble, Algorithms of Oppression: How Search Engines Reinforce Racism
From an information-studies perspective: demonstrates how commercial search engines reinforce racist and sexist tropes not merely because of “bad user data,” but because of advertising business models and market monopoly.
In English: original text written in English
In Polish: Polish edition not verified
-
critical perspective 2021 · English
Sandra Wachter, Brent Mittelstadt, Chris Russell, Bias Preservation in Machine Learning: The Legality of Fairness Metrics Under EU Non-Discrimination Law
A sharp legal critique of standard computer-science fairness metrics: splits metrics into “bias-preserving” (which freeze historical inequalities as the baseline) and “bias-transforming,” showing why most technical defaults clash with EU equality law.
In English: original text written in English
In Polish: no Polish edition
-
critical perspective 2021 · English
Kate Crawford, Atlas of AI: Power, Politics, and the Planetary Costs of Artificial Intelligence
Its chapter on classification shifts the problem from “statistical skew in a dataset” to the politics of taxonomy itself: who decided, and for what institutional purpose, how human beings are boxed into discrete labels.
In English: original text written in English
In Polish: “Atlas sztucznej inteligencji. Władza, pieniądze i środowisko naturalne”, Wydawnictwo Uniwersytetu Jagiellońskiego 2024, trans. Tadeusz Chawziuk
Primary-Source Quotes
Accordingly, we use the term bias to refer to computer systems that systematically and unfairly discriminate against certain individuals or groups of individuals in favor of others.